


Tip
Recruiter summary (20 seconds)
- Who: AI, ML & Cloud Engineer and Full-Stack Developer, who also builds WordPress sites and runs digital marketing.
- Education: M.S. Computer Science (concentration in Artificial Intelligence) · B.Sc. Information Systems.
- Proof: 49 production-grade projects with tests, CI and measured results, from RAG and LLM agents to ML models and an AWS landing zone.
- Strengths: shipping end to end (data → model → API → UI → infrastructure), honest evaluation, and security by default.
- Status: available for hire, based in the United States. Start with the featured project.
- ✅ Just shipped
distributed-ai-inference: a Go inference gateway with admission control, tenant isolation and failover on Kubernetes - ✅ Also new
aws-mlops-platform: promotion gates, drift-triggered retraining and SageMaker canary deploys - 💬 Ask me about RAG that cites its sources, guarding LLM agents with human approval, telling real model drift from noise, and testing infrastructure without an AWS account
class Rocklyn(AIEngineer, MLEngineer, CloudEngineer, FullStackDeveloper):
    """I build AI products and the cloud platforms they run on: end to end, tested, documented."""

    roles     = ["AI Engineer", "ML Engineer", "LLM / GenAI Engineer", "MLOps Engineer",
                 "Cloud & Platform Engineer", "Full-Stack Developer"]
    languages = ["Python", "TypeScript", "SQL", "HCL", "PHP"]
    education = {"M.S. Computer Science": "concentration in Artificial Intelligence",
                 "B.Sc. Information Systems": "technology in service of the business"}

    def builds(self):
        return {
            "ai":        ["grounded RAG with citations", "LLM agents with human approval",
                          "speech + vision + OCR pipelines", "classical ML with explainability"],
            "backend":   ["FastAPI services", "PostgreSQL (pgvector, job queues)", "Kafka streaming"],
            "frontend":  ["React + TypeScript dashboards"],
            "cloud":     ["AWS landing zones", "ECS / RDS / EFS", "Terraform with tests"],
            "web":       ["WordPress (Elementor, Divi, ACF)", "WooCommerce and Shopify stores"],
            "growth":    ["SEO", "GA4 + Tag Manager analytics", "Google and Meta Ads", "email and CRM"],
        }

    def principles(self):
        return [
            "Measure it: AI features ship with an evaluation, not a demo.",
            "Say \"I don't know\": answers cite their source or decline.",
            "Secure by default: least privilege, no long-lived keys, audit trails.",
            "Write it down: design docs, runbooks and known limitations in every repo.",
        ]
|
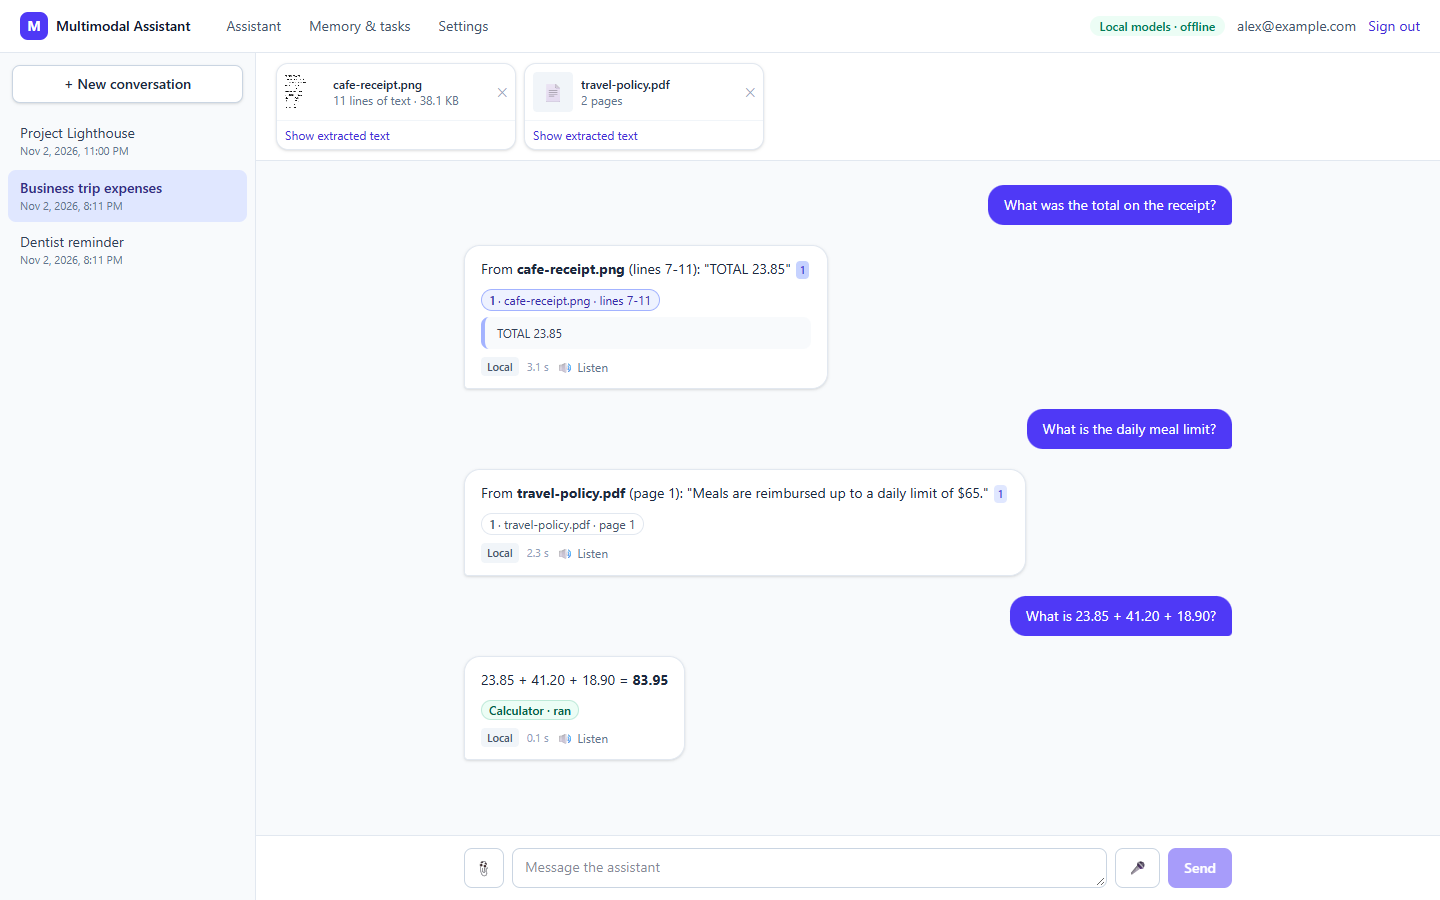
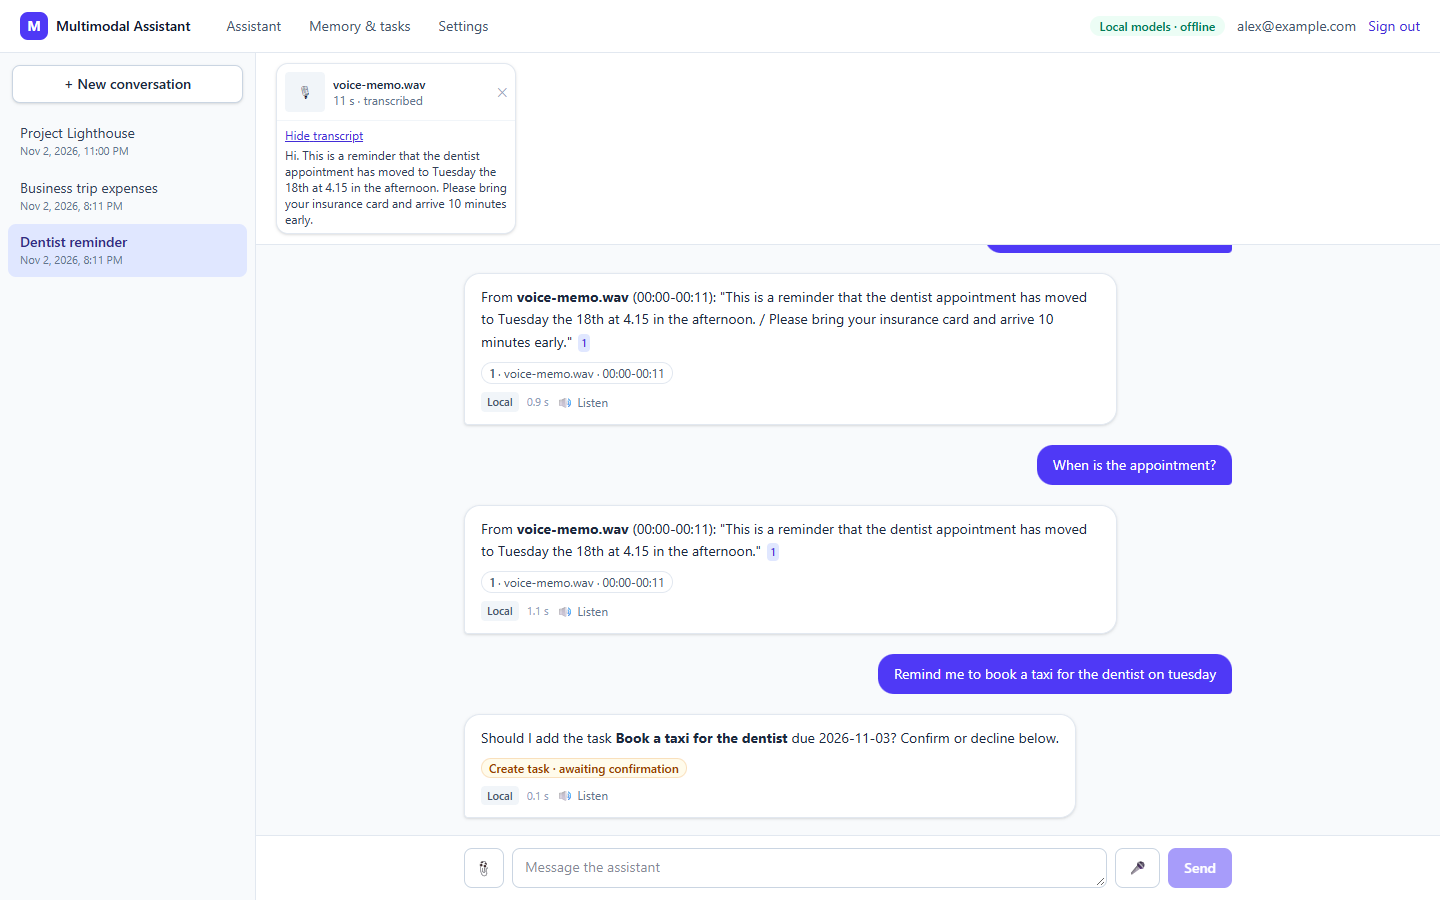
Ask about a receipt photo, a scanned PDF or a voice memo by typing or speaking. Every answer quotes its source with the page, line or timestamp. When the files don't contain the answer, it says so.
|

|
Keeps a production model healthy after it ships: data contracts, MLflow registry, promotion gates against the champion, drift and performance monitoring that retrains by itself, and SageMaker canary deploys with auto-rollback. 📊 Every drift detected in its first month · 0/12 false alarms · PR-AUC 0.64 vs 0.58 unmanaged
|
Talk or type, attach photos, PDFs and voice notes. Answers cite the page, line or timestamp, decline when the files don't say, and run tools under permissions that prompt injection can't bypass. 📊 92% grounded-answer accuracy · 4% speech WER · 0 prompt-injection data changes
|
|
A Terraform landing zone: Organizations with guardrail SCPs, tamper-resistant org-wide logging, GuardDuty and Security Hub, and a Transit Gateway network with prod/non-prod isolation. Tested without an AWS account. 📊 32 Terraform tests on a mocked provider · 0 Checkov failures · AWS quotas checked before plan
|
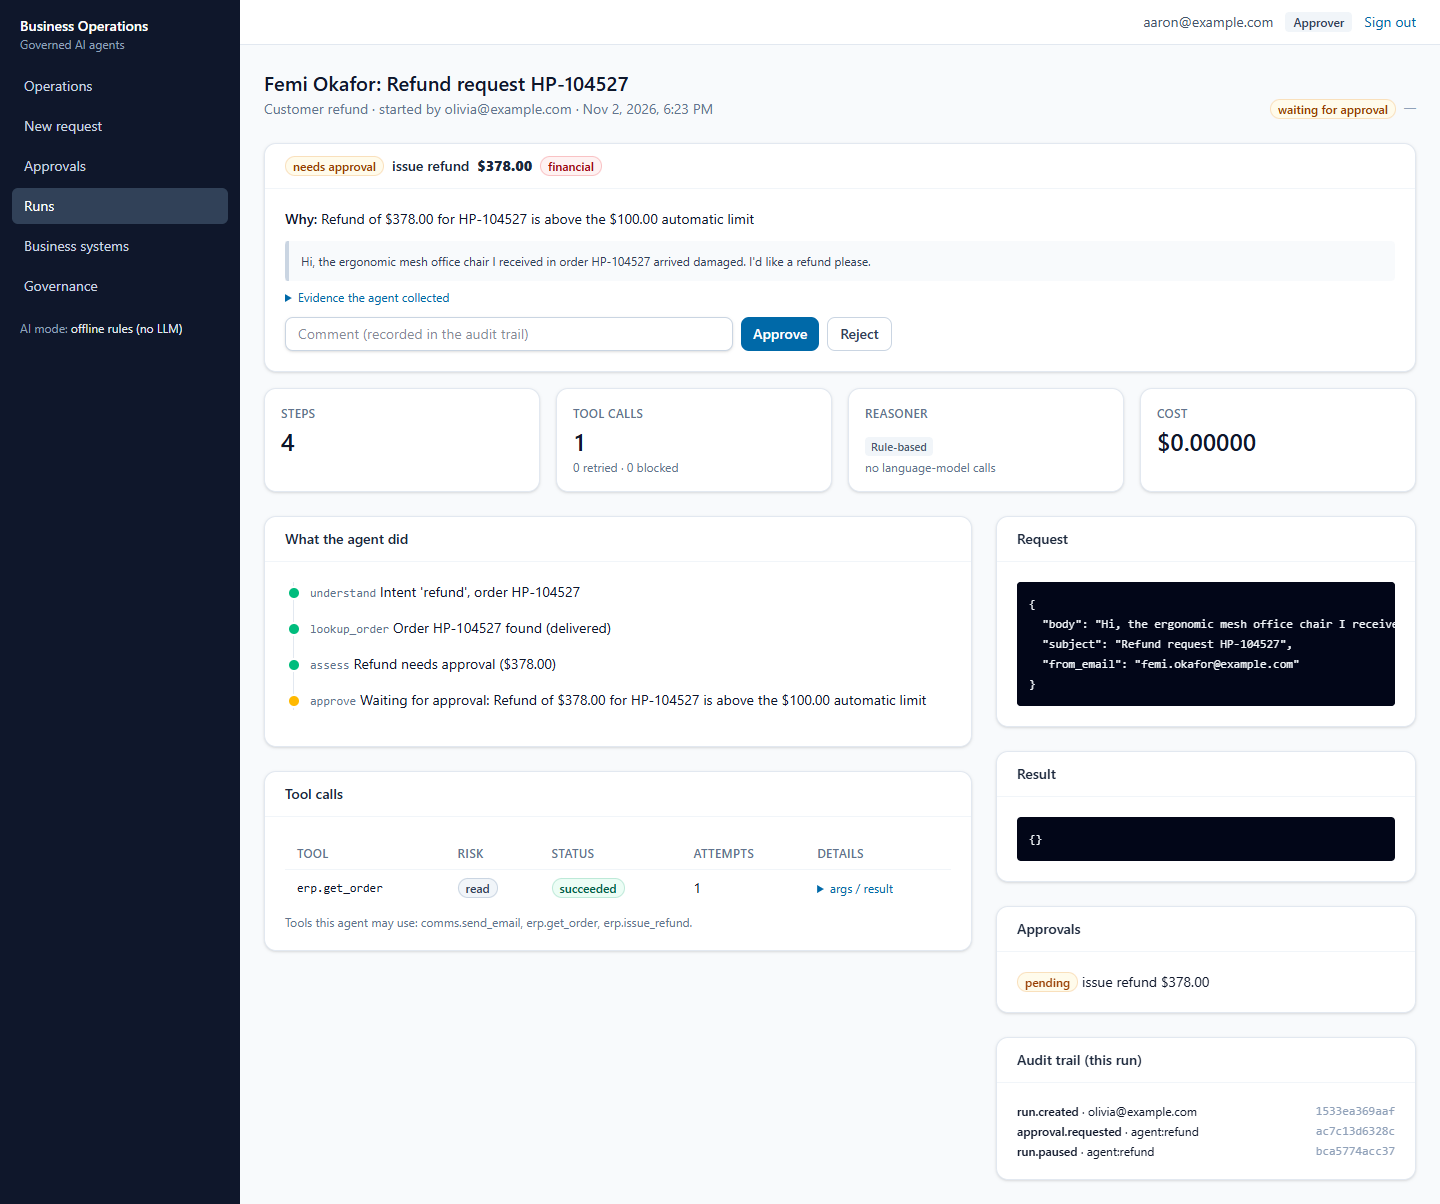
AI agents that handle refunds, supplier invoices and purchase requests, with human approval for risky actions, idempotent tools, retries and a hash-chained audit trail. 📊 96.9% correct outcomes on 129 labelled cases · 100% approval precision and recall
|
|
Real-time fraud scoring on a Kafka transaction stream, with explainable model decisions and an analyst case workflow. 📊 Catches 93% of fraud dollars at ~31 alerts/day · 96% precision in the critical band
|
Turns PDFs, Word files and scans into searchable, structured data, with grounded Q&A that refuses to answer without a citation. 📊 Retrieval recall@5 1.0 · field extraction 100% · OCR error rate 1.6%
|
|
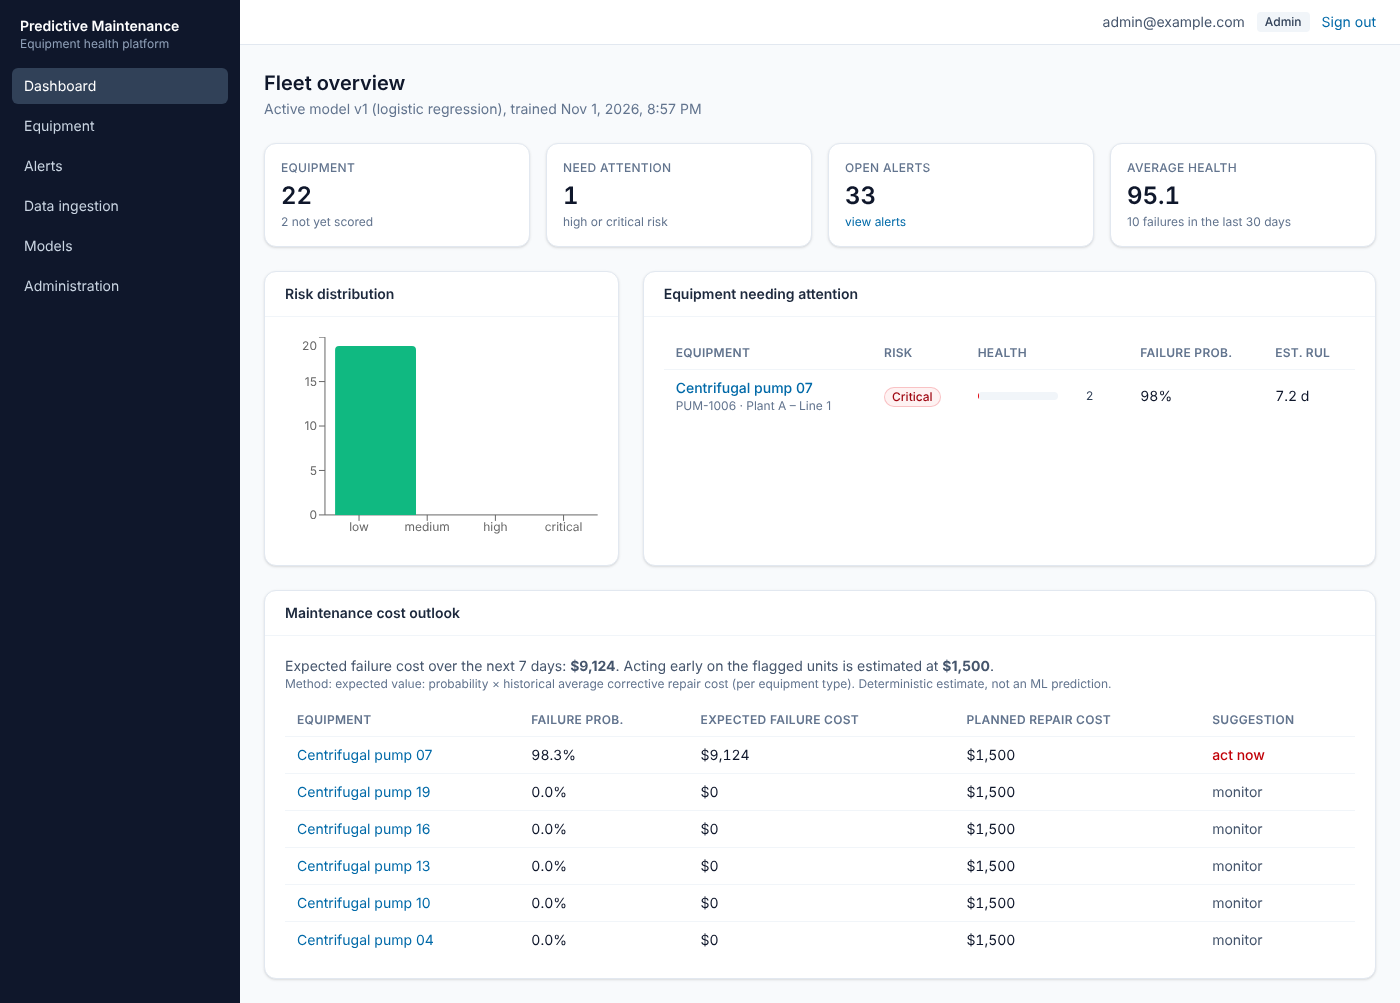
Predicts industrial equipment failures days ahead from sensor data, explains each prediction, and tracks the fleet on a dashboard. 📊 Flagged 34 of 35 held-out failures, 6.6 days ahead on average · precision 0.83
|
Team knowledge bases built from files and the web, with hybrid search, re-ranking and cited answers. 📊 Citation precision 99.3% · 100% correct "not found" · MRR 1.0 with re-ranking
|
|
Understands any codebase: parses five languages, maps dependencies, flags risks and answers questions about the code. 📊 100% precision and recall on 21 planted findings · semantic search recall@5 95%
|
Model serving that stays predictable under overload: a Go gateway with per-tenant quotas, admission control (Little's law), deadlines, fan-out and failover, in front of batching ONNX workers on Kubernetes. 📊 Overload: 38.6 vs 0.05 req/s served · noisy neighbour: 98.7% vs 23.8% · replica killed: 0 errors
|
|
Event-driven order processing with exactly-once effects under at-least-once delivery: an idempotent API, a transactional outbox, and a Step Functions saga that compensates. A fault-injection evaluation removes each mechanism to measure what it prevents. 📊 0 invariant violations under 566 injected faults · 68 double charges prevented · $130 per million orders
|
Detect AWS misconfigurations as they happen (CloudTrail → EventBridge), fix the safe ones behind exemptions, a re-check, a circuit breaker and an exact rollback, and find IAM privilege-escalation paths, not just wildcards. 📊 100% precision/recall on 446 labelled findings (string matching: 19.5%) · 0 unintended changes in 237 fixes
|
|
Cost recommendations you can act on, from CUR 2.0: waste with evidence, rightsizing on peaks not averages, the provably optimal Savings Plan, backtested forecasts and anomalies that respect the weekly cycle. 📊 31.8% of a $115k/month run rate identified · 0 unsafe downsizes (average-CPU rule: 77) · 0 false anomaly alarms (vs 33)
|
Bronze/silver/gold that gets the numbers right when the feed does not: data contracts with quarantine, idempotent MERGE, late data, schema evolution, and snapshots with time travel and lineage. 📊 $0.00 revenue error on $19.1M (naive append: $2.24M) · 942/942 bad rows quarantined · 0 snapshots on replay
|
|
Multi-region disaster recovery measured: the four AWS DR strategies compared on RTO, RPO and cost, and a guarded failover controller (quorum, error-rate alarm, hysteresis, fencing) against a naive one. 📊 3.4 min RTO p95 active-active (backup and restore: 105 min) · 0 split-brain writes (naive: 19,082) · 0/20 false failovers
|
A security gateway in front of any LLM: prompt-injection detection (including hidden in documents and obfuscated), PII redaction and restoration, output checks for leaks and phishing links, rate limits and budgets. 📊 0% attack success (no gateway: 100%, keywords: 91%) · 90% of hand-written attacks caught · 3.1 ms p95
|
|
Evaluation that holds up: judges calibrated against human labels (kappa), debiased pairwise judging, paired tests with Holm correction, and a slice-aware release gate with measured false alarms and power. 📊 kappa 0.91 vs humans (uncalibrated 0.51) · 96% of slice regressions blocked at 2.5% false alarms · overall-mean gate: 1.5%
|
Recommendations measured honestly: EASE, implicit ALS, BPR and item-kNN against popularity on a temporal split, tuned on validation, a cold-start hybrid, and a serving API. 📊 +29% NDCG over popularity (CI +0.034 to +0.043) · cold-start NDCG 2.8x · a random split flatters by 65%
|
|
Hierarchical, probabilistic forecasting: a global quantile GBM, conformal intervals, bottom-up / WLS / MinT reconciliation, a rolling backtest, and costed stock decisions. 📊 36% less error than seasonal naive · coverage 72% → 81.8% for an 80% interval · stock cost −51%
|
Which records are the same person: multi-key blocking, a learned matcher with nickname- and typo-aware features, and average-linkage clustering that won't chain look-alikes together. 📊 F1 0.986 on unseen people (rules 0.930) · 4.9x fewer errors · twins merged 1.3% (connected components: 33%)
|
|
A/B tests that keep their promises: CUPED, an always-valid sequential test for teams that peek, SRM checks, the delta method and FDR control, all measured on simulated experiments. 📊 peeking: 26.6% false positives → 0.7% · CUPED −22% variance · slicing false finds 36% → 4.6%
|
Training sets that see what serving sees: point-in-time joins as known at each moment, an online store that matches offline exactly, and skew detection, with the leakage it prevents measured. 📊 0 of 44,000 rows differ from serving · label-date leak: AUC 1.00 offline → 0.71 in production · pence bug caught on 4/4 amount features
|
|
Unsupervised defect detection on CPU: a PatchCore-style patch memory with a greedy coreset, trained on good parts only, against pixel statistics and PCA, with image and pixel AUROC per defect. 📊 AUROC 0.974 (pixel stats 0.847, PCA 0.764) · 77% of defects caught at ~4% false alarms · 43 ms per image
|
Bulk, tiered, BOGO and cart discounts in integer cents, checked against an independent reference with property and mutation testing, and in real WooCommerce. 📊 0 / 20,000 carts off · 10 / 10 planted bugs caught · 2.6 ms p95 for 50,000 units
|
|
Plugin that answers visitors from the site's own pages: BM25 retrieval, Claude (official PHP SDK) with citations or an offline extractive mode, and a prompt-injection filter, evaluated on a held-out question set. 📊 Right page in top 5 96% / 100% (WP search 28% / 23.5%) · 0 injection repeats · 0.9 ms p95
|
Six Gutenberg blocks (React, 📊 0 / 59,600 open-now errors · 0 / 2,000 structured-data breaks · 3.0 KB for all six blocks
|
|
Full-site-editing theme (theme.json v3, templates, patterns, 3 style variations) with no theme JS or web fonts, a WCAG contrast gate per palette, and a same-content comparison with Twenty Twenty-Five. 📊 31% lighter than Twenty Twenty-Five · 36 / 36 contrast pairs pass AA · Lighthouse accessibility 100
|
Contact-form plugin with layered spam scoring and a durable CRM queue (lease, idempotency keys, backoff) for HubSpot, Mailchimp and webhooks, evaluated on a held-out spam set. 📊 0 / 2,400 real leads lost · 985 / 985 delivered exactly once through outages · 0 double sends
|
|
Phone receptionist on Twilio webhooks with an offline dialogue engine and a Claude agent (tool use), both behind a guarded front desk: read-back and a clear yes before any change, verified callers, prices only from the list. 📊 95% of held-out calls handled (keyword IVR 20%) · 0 wrong changes in 1,800 calls · 0 / 360 unsafe actions past the guards
|
Service desk of scoped specialist agents (Claude or offline) behind a triage agent, each acting on behalf of the requester with approvals, compared with a keyword router and a single service-account agent, plus a blast-radius test. 📊 0 / 310 hostile tickets got through (service-account agent 211) · 78.8% on fresh wording · hijacked HR agent reaches 0.85 people, not 51
|
|
Camera analytics on one CPU core: stabilised background model, Kalman + Hungarian tracker, alerts for crossings, intrusion, loitering, abandoned objects and wrong-way vehicles, and Claude answering questions over the alert store. 📊 MOTA 0.815 / IDF1 0.757 on held-out scenes · crossings 0.98 / 0.92 P/R · 25-59 fps per core
|
Supplier contracts read by two independent extractors with evidence-backed review routing, a risk playbook with redlines and approvals, a notice-deadline renewal calendar, and Claude with every value tied to a verified quote. 📊 98.8% / 72.8% of terms on two unseen templates · 100% of auto-accepted terms correct · 0 of 50 unwanted renewals missed
|
|
Progressive rollouts with side-by-side canary analysis per region, endpoint and cell, automatic rollback, test impact analysis, error-budget guardrails, and Claude rollback notes checked against the evidence. 📊 97.9% of bad versions rolled back · 1 of 208 healthy versions rolled back · 37.5% of tests run for 99.8% of bugs
|
Time-zone-aware scheduling by cost (nights, past late-meeting load, focus time) and action items from transcripts that follow the conversation, with a learned turn classifier, a review queue and Claude checked against the transcript. 📊 -76% night meeting hours · 0.72 owner/task F1 on unseen phrasing (rules: 0.00) · 96.4% of items surfaced
|
|
A developer portal whose catalog is discovered from evidence (pages, deploys, commits, traces, deploy config), with ownership disputes sent to teams, readiness scorecards, a golden path tested in CI and Claude answering catalog questions through tools. 📊 99.3% of owners right (declared catalog: 82.8%) · 7 vs 135 misrouted pages · 0.96 blast-radius recall
|
Alert storms grouped into incidents by dependency graph and logs, root causes ranked with evidence, guarded runbooks with pre-checks, verification and revert, and Claude incident updates checked against the facts. 📊 100% root cause ranked first on held-out incidents (biggest spike: 52%) · 24 vs 51 min to mitigate · 0 actions on unknown faults
|
|
Admission policies on parsed objects (CronJobs, init and ephemeral containers, security inheritance), fixes verified by the engine (automatic or Claude JSON Patches), rightsizing judged forward and upgrade blockers. 📊 policy F1 1.00 vs 0.34 on unseen manifest forms · 0 vs 92 OOM kills · CPU requests cut to 40%
|
Self-service cloud with policy checks and fixes, approval routing, vetted Terraform with mandatory tags, usage-aware cost estimates and a budget gate, and plain-English requests through Claude. 📊 8.5% median estimate error (list price: 18.6%) · underestimates by 30%+ cut from 35% to 9% · overspend $419k → $153k
|
|
Risk-based restore tests that find broken backups before a disaster, dependency-aware recovery orchestration against RTOs, and old runbooks turned into checked plans with Claude. 📊 failed tier-1 restores 331 → 80 · tier-1 back within RTO 8.5% → 65% · full recovery 133 h → 32 h
|
Booking plugin with atomic slot claims (tested under concurrent requests on real WordPress + MariaDB), opening hours resolved per date across daylight saving, and gap-aware start times; block, REST API, ICS emails, signed cancel links. 📊 0 double bookings (check-then-insert: 3) · 0 / 4,380 wrong DST days (fixed offset: 1,645) · +1.6 pts booked
|
|
Plugin updates with structural before/after page checks and verified rollback through WordPress's upgrader, plus a hub dashboard over REST with application passwords. 📊 100% of breaking updates caught on held-out sites (WordPress's error check: 34%) · 0 harmless rollbacks · 59% of post-freeze breakage kinds
|
WordPress plugin with a fair-share rota scheduler (hard rules never broken, scarcest places first, repair pass), signed accept/decline links with automatic replacement, giving statements and a sermon podcast feed. 📊 0 double bookings (team spreadsheets: 1,141/quarter) · volunteers never asked 26% → 0.1% · back-to-back Sundays 34% → 11%
|
|
A block theme for estate agents and the Parcel Listings plugin: a typed search index kept in step with every edit, dynamic blocks, and schema.org listing data. 📊 150x faster search than meta_query at 30k listings (4.7 ms vs 704 ms) · 0 different results in 450 searches · 0 axe-core violations
|
A call queue ranked by learned seriousness × reachability (cooling speed per lead source, learned from call history), a pipeline, contract deadlines in business days, and inquiry reading with Claude. 📊 +28% deals vs newest-first on held-out brokerages · serious leads never called 4,985 → 1,330 · +18% in a shifted market after retraining
|
|
Maintenance requests triaged from the tenant's own words (hazard lexicon + learned model, tested on phrasings written after the freeze), emergencies to on-call day or night, and a rent ledger that applies payments to rent before fees. Optional Claude second reading that can only raise urgency. 📊 97% of emergencies attended within 4 h vs 51% inbox order · 90% emergencies caught on unseen wording vs 15% keywords · 0 vs 1,756 pyramided late fees
|
Independent rubric panels with learned interviewer leniency, a co-panelist bias audit, schools hidden, a four-fifths check per stage, and a blind résumé screen with Claude citing evidence. 📊 group hire-rate ratio 0.58 → 0.97 on held-out companies · +0.23 SD better hires than a gut call · 37 of 53 biased interviewers found, 1 false flag
|
|
Reorder points from each SKU's forecast errors and lead-time spread (Syntetos-Boylan for intermittent items, ABC cover), velocity slotting and 2-opt pick routes, and shipping notices read with Claude against open POs. 📊 98.5% vs 92.4% fill rate at equal stock · min/max needs 1.86x the stock · 29% less walking per order
|
Routes planned windows first with cheapest insertion and moves between technicians, van kits picked for each day's jobs from fault and brand history, and job requests read with Claude into the service catalogue. 📊 appointments kept 91.7% vs 75.7% · 43% less driving per job · first-time fix 99.6% vs 72.8%
|
|
A career operating system that only says what the candidate confirmed: a Knowledge Vault where every résumé fact carries its source text, Claude extraction with quotes checked by code, and tenant isolation down to PostgreSQL row-level security. Commercial product: live demo, private code. 📊 0 facts used before confirmation · 2-layer tenant isolation · parser F1 0.77 on unseen layouts (target missed, reported)
|


|
Concentration: Artificial Intelligence Graduate-level focus on artificial intelligence and machine learning: the foundation behind the AI systems in the projects above. |
Business technology and data How technology serves a business: the reason my projects start from a real business problem and end with documentation for the people who run them. |
| AI & ML |          |
| Backend |       |
| Frontend |     |
| Cloud & DevOps |         |
| Web & growth |      full toolkit ↓ |
every_repo:
  ci:             [lint, type-check, tests, secret scan]          # green on main, every repo
  ai_features:    measured on labelled evaluation sets            # accuracy, citations, abstention, safety
  security:       least-privilege IAM, no long-lived credentials, input validation, audit trails
  infrastructure: Terraform for AWS, validated in CI, never applied without review
  docs:           [README, design doc, operations runbook, known limitations, model / AI card]
data: synthetic only, generated by code, no real customer dataBesides engineering AI systems, I build and grow websites: WordPress builds, SEO, analytics, campaigns and e-commerce. I can ship a product and help it reach the right people.
| 🧱 WordPress & page builders |      |
| 🧑💻 Web development |    |
| 🔍 SEO & site optimization |         |
| 📈 Analytics & tracking |       |
| 📣 Marketing platforms |         |
| 🛒 E-commerce & payments |      |
| 🎨 Design & creative |     |
| 🌐 Hosting, performance & accessibility |      |
| 🗂️ Workflow & AI |        |
const marketing = {
  wordpress:   "business sites with Elementor, Gutenberg, Divi or WPBakery; ACF and PHP for custom features",
  seo:         "technical audits, keyword research and Core Web Vitals fixes that move rankings",
  analytics:   "GA4, Tag Manager and Looker Studio dashboards; heatmaps and A/B tests for conversion",
  campaigns:   "Google Ads, Meta, email (Mailchimp, HubSpot, Constant Contact) and CRM automation",
  ecommerce:   "WooCommerce and Shopify stores with Stripe, PayPal and Square payments",
  quality:     "fast, secure, accessible (WCAG 2.1 / 2.2) sites on managed hosting with CDN and SSL",
};Hiring for AI, ML, cloud or full-stack work? Start with the featured project; every README opens with the problem, the design and the measured results.


Built in public, one production-grade project at a time.