
A command line tool that fills document templates with data.
Point it at a template (Word, text, Markdown, HTML or JSON) and a data source: an Excel or JSON file, or a JSON Schema that templify asks you to fill. templify renders one file per row, one file with every row in it, or one file from a single object. Before rendering, you can order, filter and group the data.
templify render --each -t offer.docx -d employees.xlsx -o offers -n nameoffers/
├── Abdullah.docx
├── Rawaa.docx
├── Rama.docx
└── Omar.docx
- Features
- Installation
- Quick start
- How it works
- Commands
- Data sources
- Templates
- Output files
- Ordering
- Filtering
- Grouping
- Cookbook
- Errors
- Extending templify
- Development
- Many template formats:
.docx,.txt,.md,.html,.htmand.json. The writer is picked automatically from the template's extension. - Many data sources: Excel (
.xlsx), JSON (.json), or answers asked from a JSON Schema (-s). - One command, three modes: every row in one file (
render), one file per row (render --each), or one object in one file (render --object). - Ordering by any number of columns, ascending or descending.
- Filtering with a JSON filter language: 50+ rules for strings, numbers, decimals, dates, datetimes and UUIDs. Rules combine with
all/any, nest, and can be inverted. - Grouping by one or more columns, e.g. one file per department listing its employees.
- Safe output: existing files are never overwritten, invalid filename characters are replaced, and missing folders are created.
- Validated JSON output: a JSON template that renders invalid JSON is rejected before anything is saved.
- Clear errors for bad templates, bad data, unknown columns and bad filters, instead of Python tracebacks.
- Extensible: add a new data reader, template writer or filter rule with one decorator.
Requires Python 3.12+.
Install it as a global command from PyPI with uv:
uv tool install templify-clior with pipx:
pipx install templify-cliOr run it from a clone without installing:
uv syncuv run templify --help1. Prepare your data, e.g. employees.xlsx. The first row holds the column names:
| name | department | city | salary | hired | |
|---|---|---|---|---|---|
| Abdullah | Sales | Homs | 1200 | 2021-04-01 | abdullah@example.com |
| Rawaa | IT | Damascus | 1800 | 2023-09-15 | rawaa@example.com |
| Rama | IT | Homs | 1500 | 2024-02-10 | rama@example.com |
| Omar | Sales | Aleppo | 1100 | 2024-11-03 |
2. Write a template that uses the column names as variables, e.g. welcome.txt:
Hello {{ name }},
You joined {{ department }} on {{ hired.strftime("%d/%m/%Y") }}.
3. Run templify:
templify render --each -t welcome.txt -d employees.xlsx -o welcome -n namewelcome/Rama.txt:
Hello Rama,
You joined IT on 10/02/2024.
The same data file is used in every example below.
render runs one pipeline:
 read data ──► order ──► filter ──► group ──► render template ──► save file(s)
 (-d / -s)    (--order)  (--filter)  (--group-by)    (-t)              (-o)
- Read: the data source becomes a list of rows, each row a set of
column: valuepairs. - Order: rows are sorted by
--ordercolumns (optional). - Filter: rows not matching
--filterare dropped (optional). - Group: rows are grouped by
--group-bycolumns (optional). - Render: the writer chosen from the template extension renders the rows.
- Save:
- by default, one file containing every row.
- with
--each, one file per row, or per group when grouping.
With --object, the data is a single object instead of a list, so steps 2 to 4 don't apply and that object is rendered into one file.
templify --help| Command | Alias | What it does |
|---|---|---|
render |
r |
Render a template with data, in one of three modes |
filters |
f |
List the filter rules and their arguments |
templify render -t <template> (-d <data> | -s <schema.json>) [--each | --object] [-o <output-dir>] [OPTIONS]The mode decides what the template sees and how many files are written:
| Mode | Data | Writes | The template sees |
|---|---|---|---|
| (default) | a list of rows | one file with all the rows | the rows as a list, objects: {% for e in objects %} |
--each |
a list of rows | one file per row (or group) | each row's columns: {{ name }}, {{ salary }} |
--object |
a single object | one file | the object as object: {{ object.name }} |
| Option | Short | Modes | Description | Default |
|---|---|---|---|---|
--template |
-t |
all | Template file. Required. | |
--data |
-d |
all | Data file. Exactly one of -d / -s is required |
|
--schema |
-s |
all | JSON Schema file, ask for the data matching it | |
--output |
-o |
all | Output directory, created if missing | current directory |
--each |
One file per row (or per group) | off | ||
--object |
The data is a single object | off | ||
--filename |
-f |
default, --object |
Output filename without extension | the template's name |
--var |
-v |
default, --object |
Name of the variable holding the data | objects / object |
--name-by |
-n |
--each |
Column whose value names each file | template-<n> |
--numbered |
--each |
Prefix each filename with its row number: 1 - Rama.docx |
off | |
--order |
default, --each |
Column to order by, -column for descending. Repeatable |
||
--filter |
default, --each |
JSON filter schema | ||
--group-by |
default, --each |
Column to group by. Repeatable | ||
--items-var |
default, --each |
Variable name holding each group's rows | items |
An option used in a mode that doesn't take it is an error, never silently ignored:
--name-by only works with --each.
team.md:
# Team report

| # | Name | Department | Salary |
|---|------|------------|-------:|
{% for e in objects -%}
| {{ loop.index }} | {{ e.name }} | {{ e.department }} | {{ "{:,}".format(e.salary) }} |
{% endfor %}
**Total salaries:** {{ objects | sum(attribute="salary") }}
templify render -t team.md -d employees.xlsx -o reports --order -salaryreports/team.md:
# Team report

| # | Name | Department | Salary |
|---|------|------------|-------:|
| 1 | Rawaa | IT | 1,800 |
| 2 | Rama | IT | 1,500 |
| 3 | Abdullah | Sales | 1,200 |
| 4 | Omar | Sales | 1,100 |

**Total salaries:** 5600
Rename the output and the loop variable:
templify render -t team.md -d employees.xlsx -o reports -f "2024 team" -v employeesThe template then loops with {% for e in employees %}, and the file is saved as reports/2024 team.md.
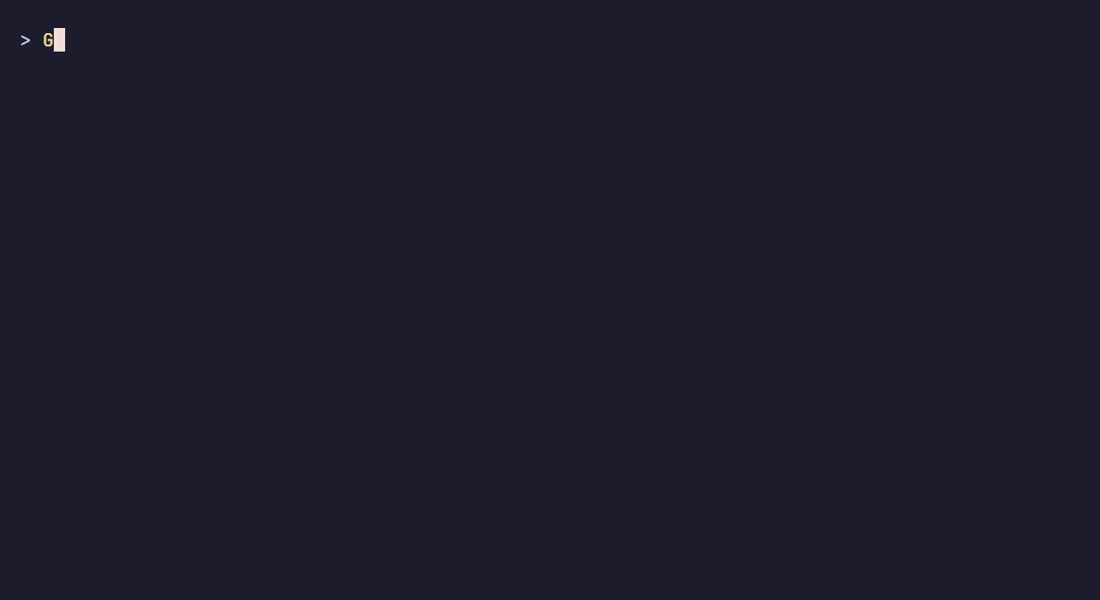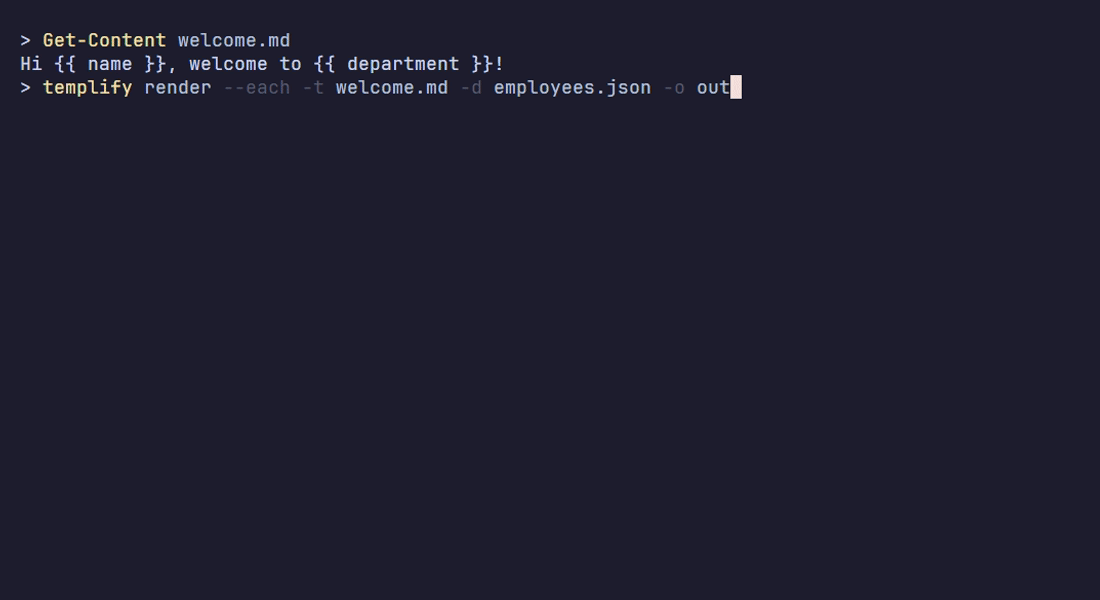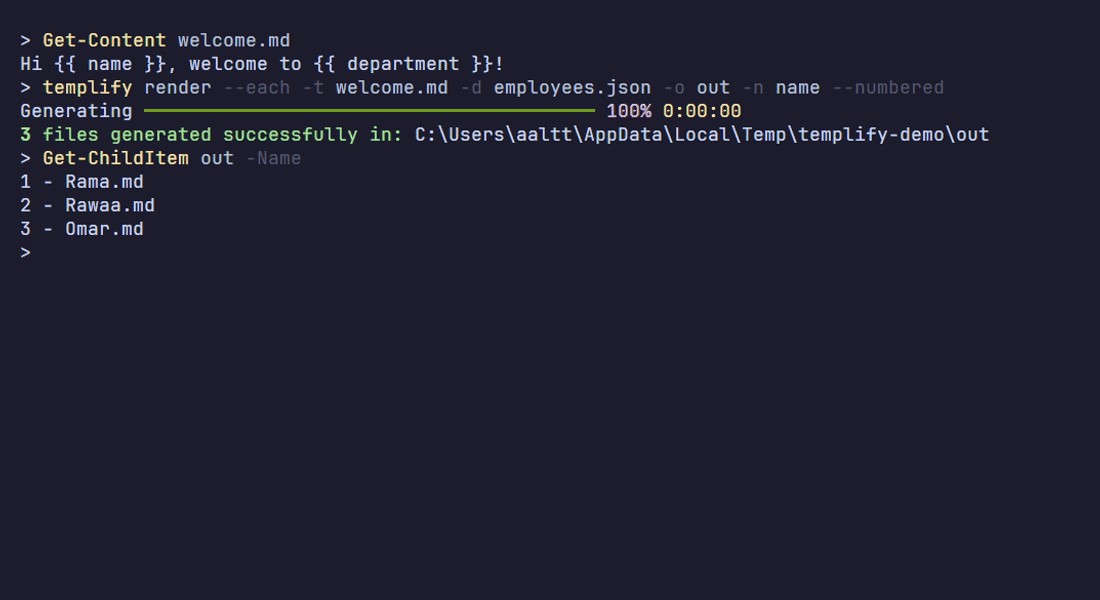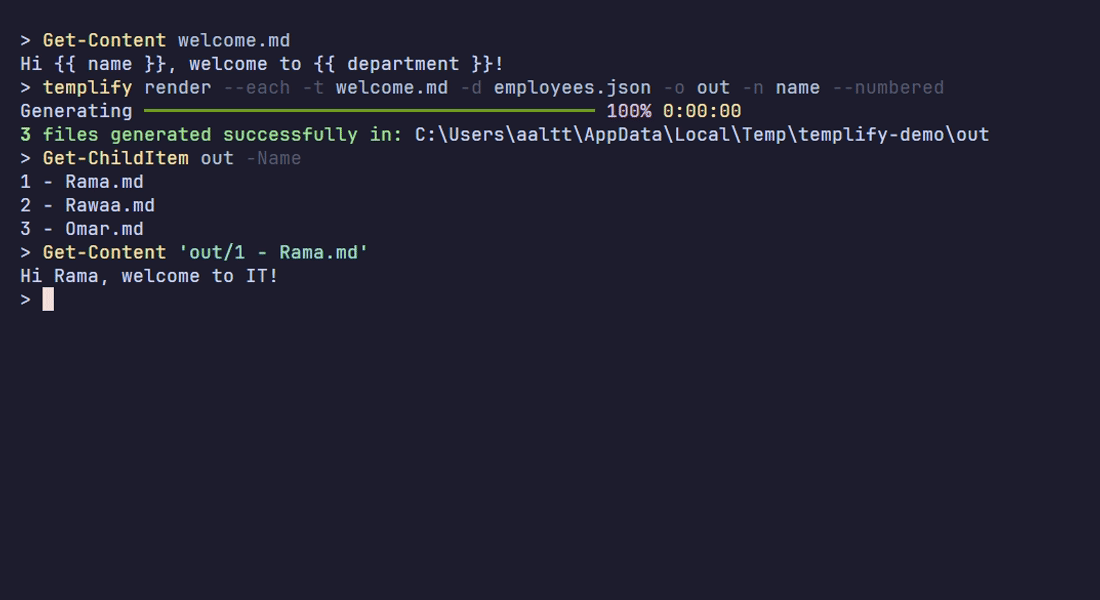
templify render -t offer.docx -d employees.xlsx -o offers --each -n name --numberedoffers/
├── 1 - Abdullah.docx
├── 2 - Rawaa.docx
├── 3 - Rama.docx
└── 4 - Omar.docx
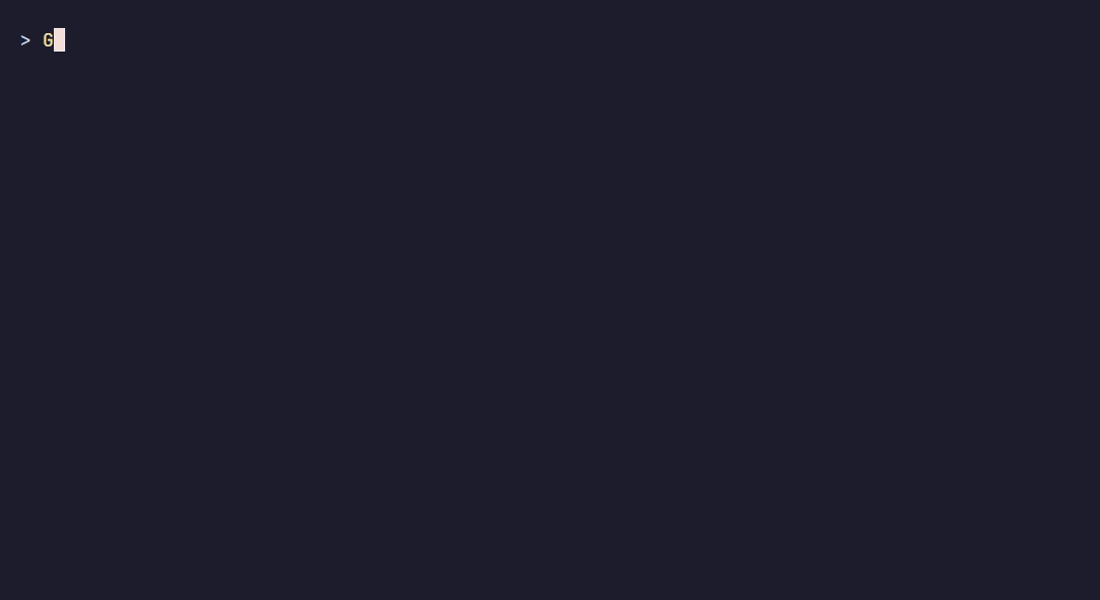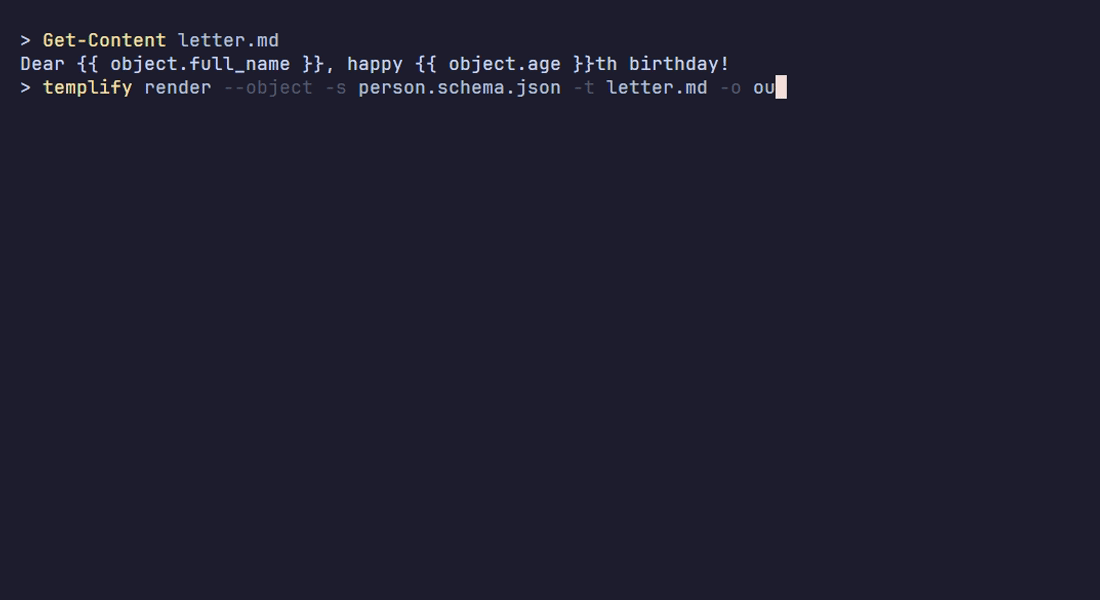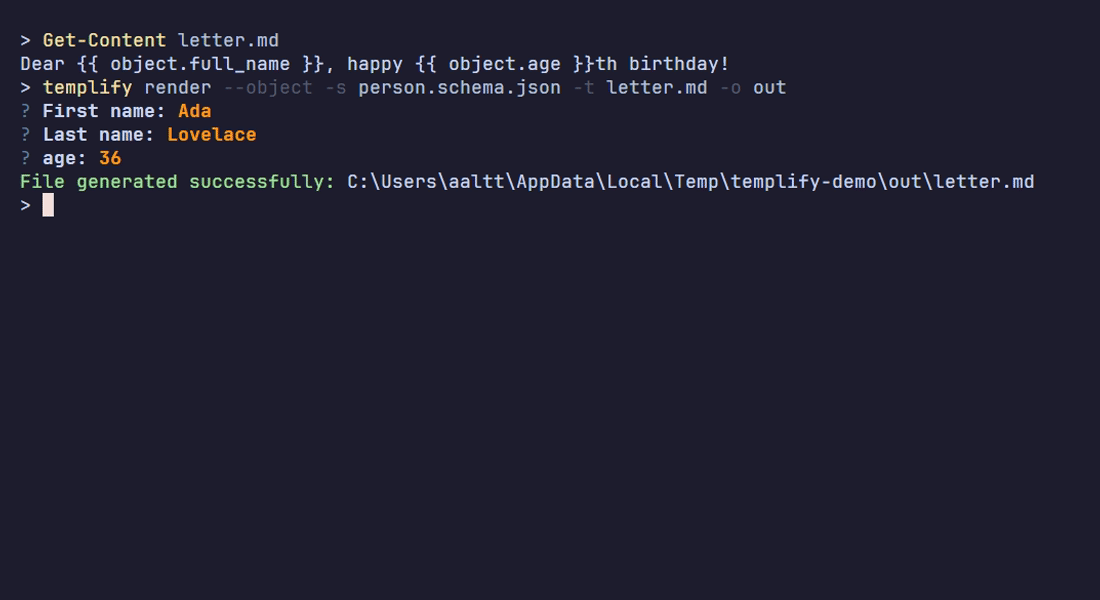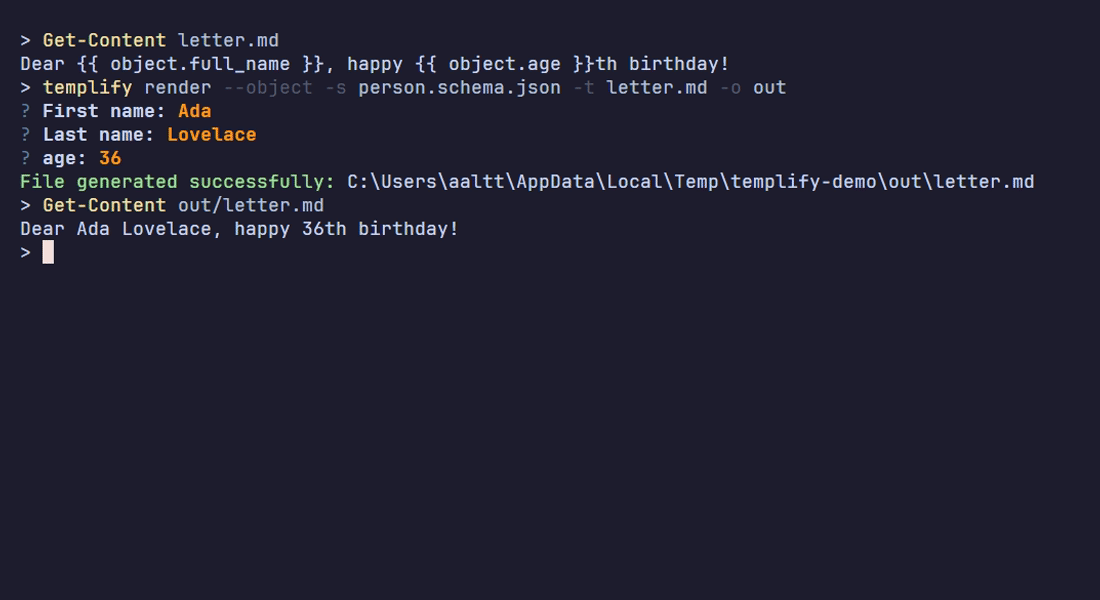
templify render -t letter.docx -d rama.json --object            # Hello {{ object.name }}
templify render -t letter.docx -s person.schema.json --object   # asks for the fields first
With -s, schemify asks for the fields:
Lists every filter rule you can use in --filter, with its arguments (in args order) and description:
templify filters Rule Arguments Description
is_true key: string Keep records where `key` is `true`.
is_null key: string Keep records where `key` is empty (`null`).
int__eq key: string, value: integer Keep records where `key` equals `value`.
...
string__regex key: string, pattern: string Keep records where `key` matches the regular expression `pattern`.
string__is_in key: string, value: list[string] Keep records where `key` is one of the `value` list.
...
date__ge key: string, value: date Keep records where `key` is greater than or equal to `value`, comparing the day only.
...
The argument names are also the kwargs names: {"key": "salary", "value": 1400}.
| 0.2 | 0.3 |
|---|---|
templify single-template / s |
templify render |
templify multiple-templates / m |
templify render --each |
templify schema-template / js |
templify render --object -s ... |
templify schema-list-template / jsl |
templify render -s ... |
templify filters-json-schema / fjs |
templify filters |
-k / --filename-key |
-n / --name-by |
-i / --index |
--numbered |
--group-items |
--items-var |
-v / --data-variable, default data |
-v / --var, default objects |
-o required |
-o optional, default current directory |
| Template errors exit with code 2 | exit with code 1 (usage errors stay 2) |
render takes exactly one data source:
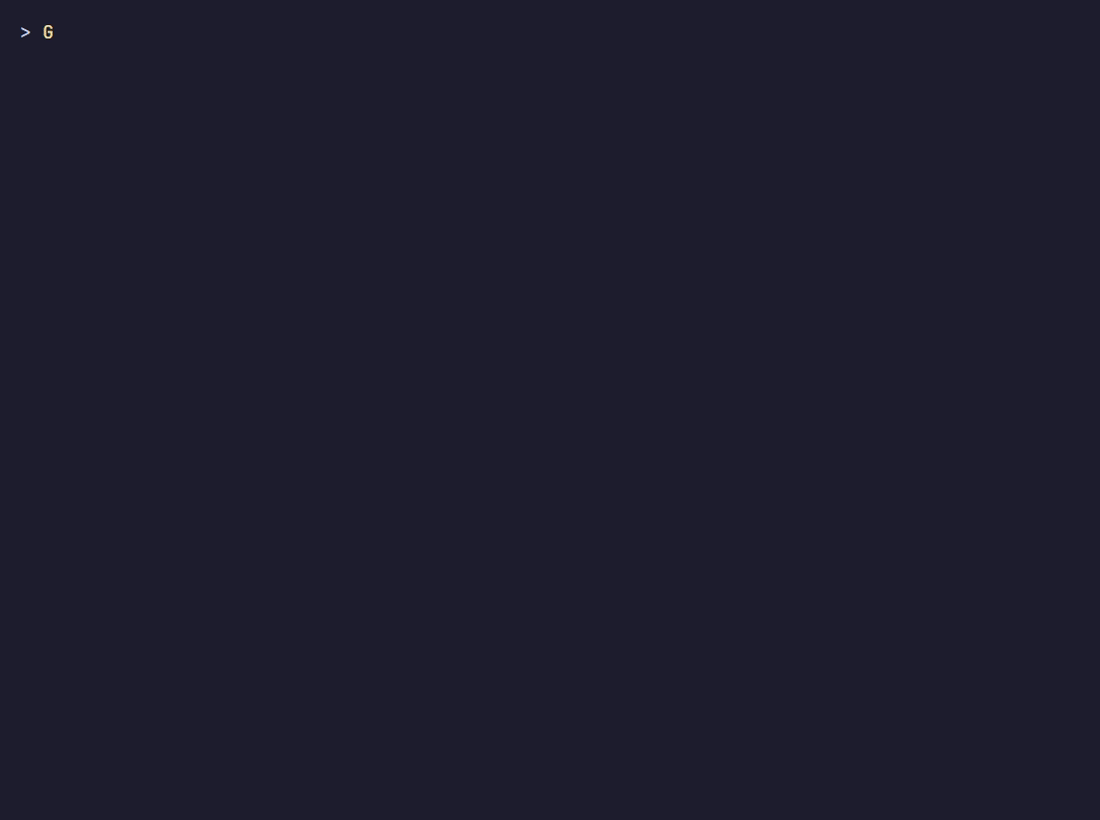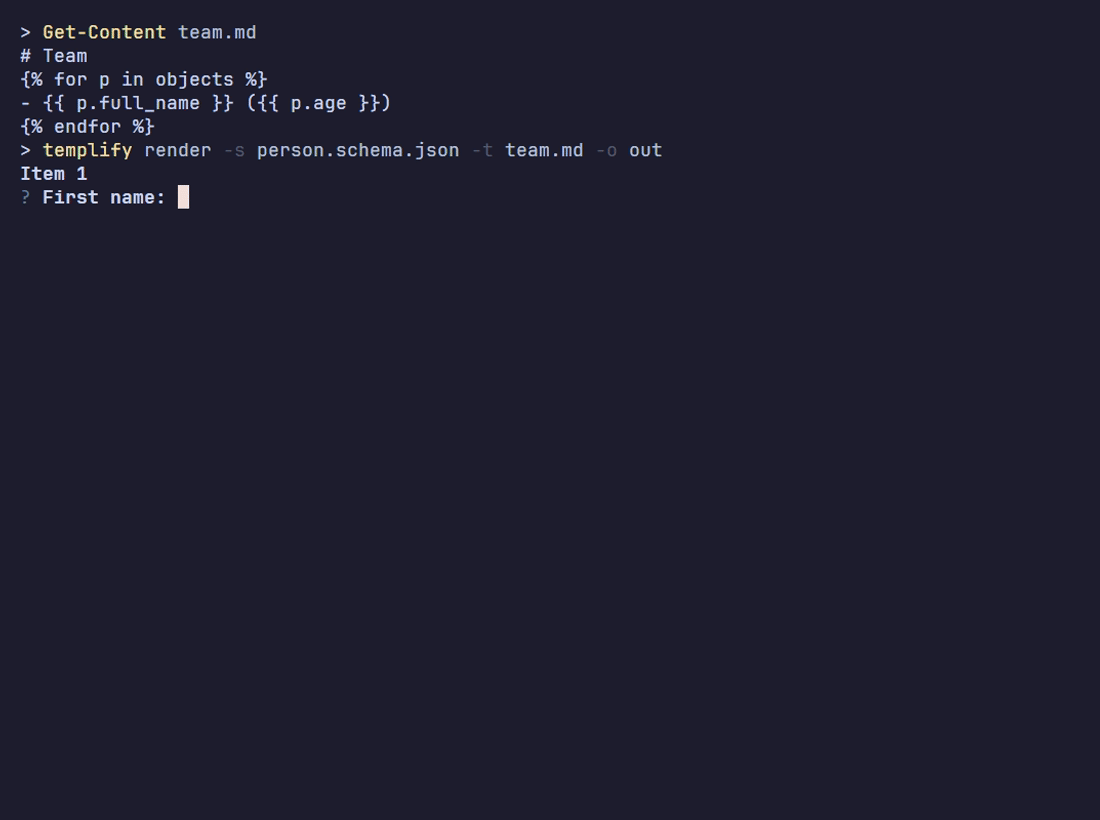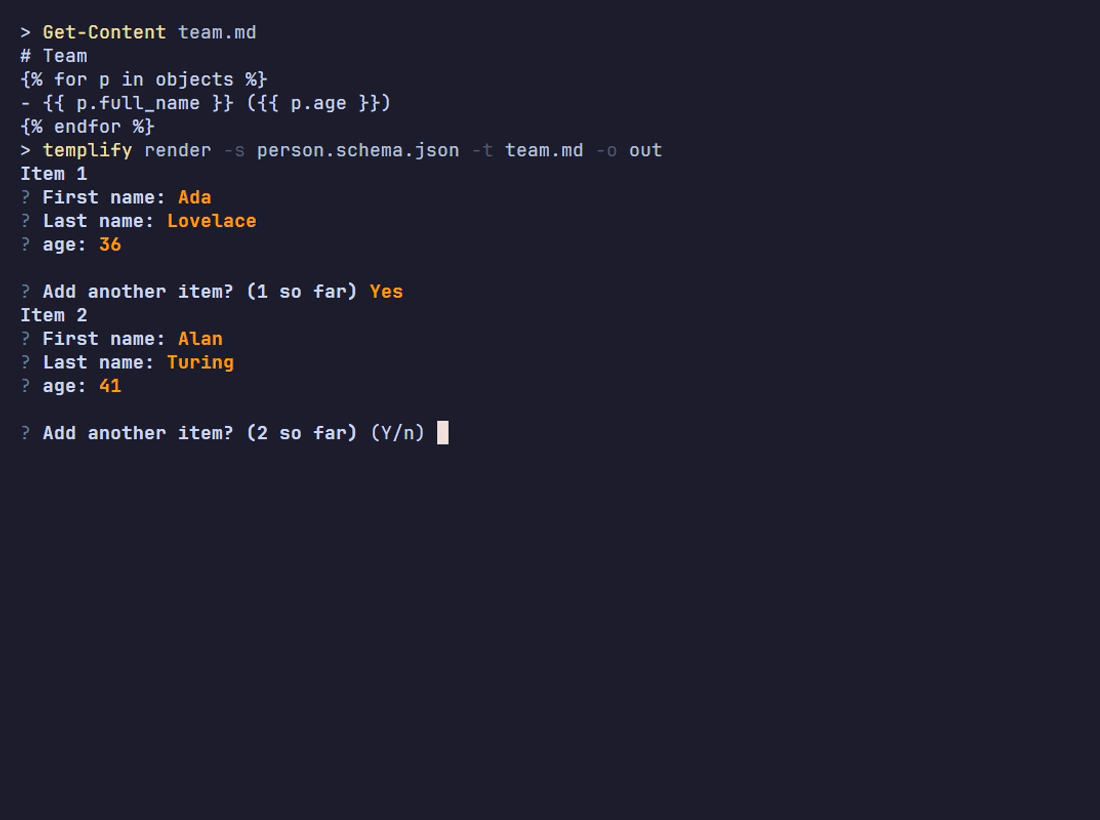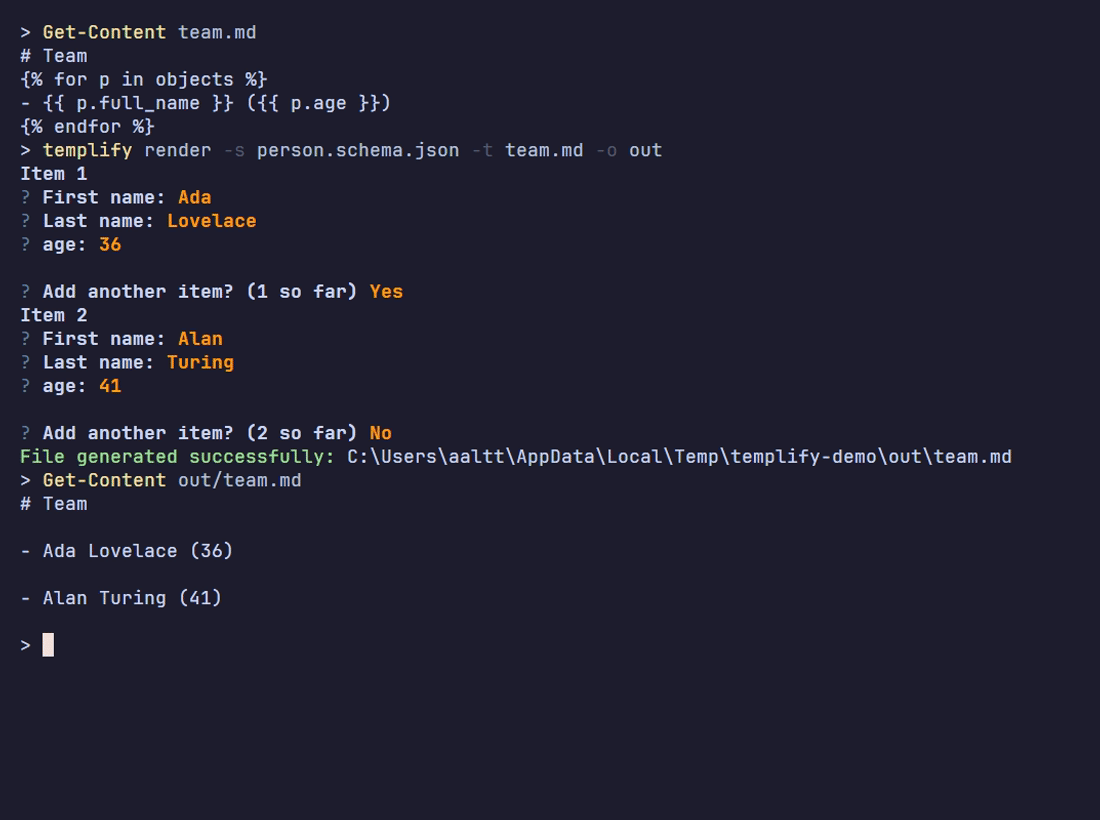
-d/--data: a data file. The reader is chosen from its extension, ignoring case.-s/--schema: a JSON Schema file. schemify asks for the data matching it: a list (keep answering until you say No), or one object with--object.
Data files for the default mode and --each hold a list of objects:
| Extension | Format |
|---|---|
.xlsx |
Excel workbook: the active sheet, first row = column names |
.json |
A JSON list of objects: [{"name": "Rama", ...}, ...] |
Data files for --object hold a single object:
| Extension | Format |
|---|---|
.json |
A JSON object: {"name": "Rama", ...} |
Excel notes
- The first row holds the column names, and each following row is one record.
- Fully blank rows are skipped.
- Formula cells give their last calculated value, not the formula text. A file created by a script and never opened in Excel has no calculated values yet, so those cells come back empty.
- Values keep their type: numbers stay numbers, dates become Python
datetimes (so{{ hired.strftime("%Y") }}works), and empty cells becomeNone.
JSON notes
- Must be a list of objects. An object, a list of numbers and so on are rejected with a clear error.
- Read as UTF-8, so Arabic and other non-Latin text works.
- JSON has no date type, so dates are strings (
"2024-02-10"). Thedate__*filter rules understand both forms.
employees.json:
[
  {
    "name": "Abdullah",
    "department": "Sales",
    "city": "Homs",
    "salary": 1200,
    "hired": "2021-04-01",
    "email": "abdullah@example.com"
  }
]The writer is chosen from the template extension, ignoring case. The output file gets the same extension.
| Extension | Writer | Engine |
|---|---|---|
.docx |
DocxWriter |
docxtpl (Jinja2 inside Word) |
.txt, .md, .html, .htm |
TextWriter |
Jinja2 |
.json |
JsonWriter |
Jinja2 + validates that the output is JSON |
Any other extension is rejected, and the error lists the supported ones.
All templates use Jinja2 syntax:
| Syntax | Meaning |
|---|---|
{{ name }} |
Print a variable |
{{ e.name }} or {{ e["name"] }} |
Print a field of a row |
{% for e in objects %} ... {% endfor %} |
Loop |
{{ loop.index }} |
1-based loop counter |
{% if salary > 1400 %} ... {% endif %} |
Condition |
{{ name | upper }} |
Filter: upper, lower, title, length, sum, default, tojson, ... |
{{ email or "no email" }} |
Fallback for empty values |
{{ hired.strftime("%d/%m/%Y") }} |
Format an Excel date |
{{ "{:,.2f}".format(salary) }} |
Format a number: 1,200.00 |
{# comment #} |
Comment, not rendered |
{%- ... -%} |
Trim the whitespace around a tag |
{% include "header.txt" %} |
Include another file from the template's folder (text formats) |
A variable that doesn't exist renders as an empty string instead of failing.
These are always available, in both modes:
| Variable | Value | In .docx it becomes |
|---|---|---|
{{ new_line }} |
\n |
a line break |
{{ tab }} |
\t |
a tab |
{{ page_break }} |
\f |
a page break |
If your data has a column with one of these names, the built-in value wins.
Write Jinja2 tags directly in the Word document. Keep each tag in the same formatting (don't bold half of {{ name }}), otherwise Word splits it into pieces and Jinja can't read it.
offer.docx:
Dear {{ name }},
Welcome to the {{ department }} team in {{ city }}. Your salary is {{ salary }}$.
docxtpl adds special tags for Word structure:
| Tag | Use |
|---|---|
{%p for e in objects %} ... {%p endfor %} |
Loop over paragraphs: each tag sits on its own paragraph |
{%tr for e in objects %} ... {%tr endfor %} |
Loop over table rows: one row per record |
{%tc ... %} |
Loop over table cells |
{%r ... %} |
Tag applied to a run |
One Word file, one page per employee (all-offers.docx, three paragraphs):
{%p for e in objects %}
{{ e.name }} - {{ e.department }}{{ page_break }}
{%p endfor %}
templify render -t all-offers.docx -d employees.xlsx -o offersA Word table with one row per employee: create a 2-row table. Put {%tr for e in objects %} and {%tr endfor %} in rows of their own, around a row containing {{ e.name }}, {{ e.salary }}, ...
See the docxtpl documentation for images, rich text and more.
A .json template is rendered like text, then validated. If the result isn't valid JSON, nothing is saved and you get an error that points at the problem.
Always write values through the tojson filter. It adds quotes and escapes characters like " for you, and turns None into null and True into true.
profile.json:
{
  "name": {{ name | tojson }},
  "department": {{ department | tojson }},
  "email": {{ email | tojson }},
  "senior": {{ (salary > 1400) | tojson }}
}
templify render --each -t profile.json -d employees.json -o profiles -n nameprofiles/Omar.json:
{
  "name": "Omar",
  "department": "Sales",
  "email": null,
  "senior": false
}
Dump the whole (ordered / filtered / grouped) dataset:
{{ objects | tojson(indent=2) }}templify render -t all.json -d employees.xlsx -o export -f employees --order name
tojsonsorts object keys alphabetically.
Why use tojson? With "name": "{{ name }}", a name like Ra"ma produces broken JSON:
Invalid value: Template Error: Rendered output is not valid JSON: Expecting ',' delimiter: line 1 column 14 (char 13)
department.html:
<!DOCTYPE html>
<html>
<body>
  <h1>{{ department }} department</h1>
  <ul>
  {%- for e in items %}
    <li>{{ e.name }} ({{ e.city }})</li>
  {%- endfor %}
  </ul>
  <p>{{ items | length }} employees</p>
</body>
</html>
templify render --each -t department.html -d employees.xlsx -o departments --group-by department -n departmentValues are not HTML-escaped, so
<b>in your data stays bold. If the data isn't trusted, escape it with{{ value | e }}.
| Situation | Result |
|---|---|
No -n |
template-1.txt, template-2.txt, ... |
-k name |
Rama.txt |
-k name -i |
3 - Rama.txt |
The -n column is empty or missing for a row |
That row falls back to template-<n>.txt |
The value has invalid characters: a/b:c? |
They become _: a_b_c_.txt |
The value is a number: -k id |
42.txt |
| The file already exists | A short random suffix is added: Rama-3f9a1c2e.txt. Nothing is ever overwritten |
| The output folder doesn't exist | It is created, including parent folders |
render without -f |
Named after the template: team.md → team.md |
Output files are written as UTF-8, with the template's line endings kept as they are.
--order <column> sorts ascending, and --order -<column> sorts descending. Repeat it to sort by several columns. The first one has the highest priority.
# highest salary first
templify render -t names.txt -d employees.xlsx -o out --order -salary

# by department A→Z, then by salary high→low inside each department
templify render -t names.txt -d employees.xlsx -o out --order department --order -salary
Rawaa Rama Abdullah Omar
Ordering by a column that doesn't exist fails with the list of available columns.
--filter takes a JSON string that describes which rows to keep.
Quoting on the command line
- bash / zsh / PowerShell 7.3+: wrap the JSON in single quotes:
--filter '{"name": ...}'- cmd.exe: escape the inner quotes:
--filter "{\"name\": ...}"
A single rule (a predicate) has exactly four keys:
{
  "name": "string__eq",
  "args": ["department", "IT"],
  "kwargs": {},
  "inverse": false
}| Key | Meaning |
|---|---|
name |
Rule name, see the rules reference |
args |
Positional arguments: the column first, then the value(s) |
kwargs |
The same arguments by name, e.g. {"key": "salary", "value": 1400}. Use {} otherwise |
inverse |
true negates the rule: "NOT equal", "does NOT contain", ... |
# IT only
templify render -t names.txt -d employees.xlsx -o out \
  --filter '{"name": "string__eq", "args": ["department", "IT"], "kwargs": {}, "inverse": false}'
# → Rawaa Rama

# everyone except IT
templify render -t names.txt -d employees.xlsx -o out \
  --filter '{"name": "string__eq", "args": ["department", "IT"], "kwargs": {}, "inverse": true}'
# → Abdullah Omar

# same rule, arguments by name
templify render -t names.txt -d employees.xlsx -o out \
  --filter '{"name": "int__gt", "args": [], "kwargs": {"key": "salary", "value": 1400}, "inverse": false}'
# → Rawaa Rama
Combine rules with an expression: exactly two keys, operator and expressions.
operator |
Keeps a row when |
|---|---|
all |
every expression matches (AND) |
any |
at least one matches (OR) |
# in Homs AND earning at least 1300
templify render -t names.txt -d employees.xlsx -o out --filter '{
  "operator": "all",
  "expressions": [
    {"name": "string__eq", "args": ["city", "Homs"], "kwargs": {}, "inverse": false},
    {"name": "int__ge", "args": ["salary", 1300], "kwargs": {}, "inverse": false}
  ]
}'
# → Rama

# in Aleppo OR earning more than 1700
templify render -t names.txt -d employees.xlsx -o out --filter '{
  "operator": "any",
  "expressions": [
    {"name": "string__eq", "args": ["city", "Aleppo"], "kwargs": {}, "inverse": false},
    {"name": "int__gt", "args": ["salary", 1700], "kwargs": {}, "inverse": false}
  ]
}'
# → Rawaa Omar
Expressions nest to any depth:
# IT AND (in Damascus OR hired since 2024)
templify render -t names.txt -d employees.xlsx -o out --filter '{
  "operator": "all",
  "expressions": [
    {"name": "string__eq", "args": ["department", "IT"], "kwargs": {}, "inverse": false},
    {
      "operator": "any",
      "expressions": [
        {"name": "string__eq", "args": ["city", "Damascus"], "kwargs": {}, "inverse": false},
        {"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}
      ]
    }
  ]
}'
# → Rawaa Rama
Empty cells: a comparison rule on an empty cell (e.g.
string__endswithon a missing email) stops withFilter failed on a data value (empty cell or wrong type?). Skip empty cells first by adding{"name": "is_null", "args": ["email"], "kwargs": {}, "inverse": true}to anallexpression.
The first argument is always the column. value is converted to the rule's type, so "5" works for int__eq.
| Rule | Arguments | Keeps rows where |
|---|---|---|
is_true |
[column] |
the value is true |
is_null |
[column] |
the value is empty / null |
| Suffix | Arguments | Keeps rows where |
|---|---|---|
eq |
[column, value] |
column == value |
gt |
[column, value] |
column > value |
ge |
[column, value] |
column >= value |
lt |
[column, value] |
column < value |
le |
[column, value] |
column <= value |
For example: int__ge, float__lt and decimal__eq. For decimal__*, the value can be a string ("10.50"), an integer, or a float rounded to 2 decimals.
| Rule | Arguments | Keeps rows where |
|---|---|---|
string__eq |
[column, text] |
equals text |
string__contains |
[column, text] |
contains text |
string__icontains |
[column, text] |
contains text, ignoring case |
string__startswith |
[column, text] |
starts with text |
string__istartswith |
[column, text] |
starts with text, ignoring case |
string__endswith |
[column, text] |
ends with text |
string__iendswith |
[column, text] |
ends with text, ignoring case |
string__is_in |
[column, [a, b]] |
is one of the list |
string__iis_in |
[column, [a, b]] |
is one of the list, ignoring case |
string__regex |
[column, pattern] |
matches the regular expression |
string__length_eq |
[column, n] |
length == n (also _gt, _ge, _lt, _le) |
# lives in Homs or Aleppo
--filter '{"name": "string__is_in", "args": ["city", ["Homs", "Aleppo"]], "kwargs": {}, "inverse": false}'
# → Abdullah Rama Omar

# name starts with "Ra"
--filter '{"name": "string__regex", "args": ["name", "^Ra"], "kwargs": {}, "inverse": false}'
# → Rawaa Ramadate__eq, date__gt, date__ge, date__lt, date__le, with arguments [column, "YYYY-MM-DD"].
They compare the day only and accept every form a date comes in:
- Excel date cells, where the time part is ignored
- ISO strings from JSON:
"2024-02-10"or"2024-02-10T08:30:00"
# hired in 2024 or later (Excel dates)
templify render -t names.txt -d employees.xlsx -o out \
  --filter '{"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}'
# → Rama Omar

# hired before 2024 (JSON string dates)
templify render -t names.txt -d employees.json -o out \
  --filter '{"name": "date__lt", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}'
# → Abdullah Rawaa

# hired during 2024: combine two rules
--filter '{"operator": "all", "expressions": [
  {"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false},
  {"name": "date__le", "args": ["hired", "2024-12-31"], "kwargs": {}, "inverse": false}
]}'datetime__eq, datetime__gt, datetime__ge, datetime__lt, datetime__le, with arguments [column, "YYYY-MM-DDTHH:MM:SS"]. They compare down to the second. The column must hold real datetimes, i.e. Excel date cells. For JSON string dates, use date__*.
uuid__eq, uuid__gt, uuid__ge, uuid__lt, uuid__le, with arguments [column, "uuid-string"].
--group-by <column> merges rows that share the same value into one group. Each group is a new row holding:
- the group-by column(s), with the shared value
items(rename it with--items-var), the list of the original rows in that group
rows:                                  groups (--group-by department):
{name: Abdullah, department: Sales}    {department: Sales, items: [Abdullah, Omar]}
{name: Rawaa,    department: IT}   ──► {department: IT,    items: [Rawaa, Rama]}
{name: Rama,     department: IT}
{name: Omar,     department: Sales}
Groups appear in the order their first row appears. Grouping runs after ordering and filtering, so --order also sorts the rows inside every group, and --filter decides which rows get grouped.
One file per group, with render --each: -n can name files after the group column.
templify render --each -t department.html -d employees.xlsx -o departments --group-by department -n departmentdepartments/
├── Sales.html
└── IT.html
One report of all groups, with render: loop over groups, then over each group's rows.
by-city.txt:
{% for group in objects -%}
{{ group.city }} / {{ group.department }}:
{%- for e in group.people %} {{ e.name }}{% endfor %}
{% endfor %}
templify render -t by-city.txt -d employees.xlsx -o out \
--order city --group-by city --group-by department --items-var peopleAleppo / Sales: Omar
Damascus / IT: Rawaa
Homs / Sales: Abdullah
Homs / IT: Rama
Useful group-level expressions:
{{ items | length }}                        {# rows in the group #}
{{ items | sum(attribute="salary") }}       {# total of a column #}
{{ items | map(attribute="name") | join(", ") }}   {# "Rawaa, Rama" #}
{{ (items | sum(attribute="salary")) / (items | length) }}   {# average #}
Grouping errors
| Problem | Message |
|---|---|
| The column doesn't exist | Key 'country' not found in data, Available keys: ... |
--items-var equals a group-by column |
Items key 'city' can not be one of the group by keys |
| The column holds lists or objects (JSON) | Can not group by unhashable values ... |
Offer letters in Word, one per employee, numbered:
templify render --each -t offer.docx -d employees.xlsx -o offers -n name --numberedOnly employees hired this year, newest first:
templify render --each -t offer.docx -d employees.xlsx -o new-hires -n name --order -hired \
  --filter '{"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}'
Emails only for people who have an email address:
templify render --each -t email.txt -d employees.xlsx -o emails -n email \
  --filter '{"name": "is_null", "args": ["email"], "kwargs": {}, "inverse": true}'
A Markdown salary report per department:
department.md:
# {{ department }}

{% for e in items -%}
- {{ e.name }}: {{ e.salary }}
{% endfor %}
Total: {{ items | sum(attribute="salary") }}
templify render --each -t department.md -d employees.xlsx -o reports -n department --group-by department --order -salaryConvert Excel to JSON:
templify render -t all.json -d employees.xlsx -o export -f employeeswith all.json containing {{ objects | tojson(indent=2) }}.
One JSON file per record, for an API import:
templify render --each -t profile.json -d employees.xlsx -o api -n emailA single printable Word file, one page per employee:
templify render -t all-offers.docx -d employees.xlsx -o print --order nameName files with two columns: templify names files from one column, so add a combined column to your data (an Excel formula like =A2&" - "&B2 works once the file is saved in Excel), then use -n full_title.
templify reports problems as short messages. Bad input (options, data, template files) exits with code 2; a template that fails while rendering exits with code 1:
| Problem | Example message |
|---|---|
| Unsupported template extension | Template extension 'pdf' is not supported, supported: docx, htm, ... |
| Unsupported data extension | Extension 'csv' is not supported for being a data file |
Both or neither of -d / -s |
Give exactly one data source: -d / --data or -s / --schema |
| Option used in the wrong mode | --name-by only works with --each |
--each with --object |
--each and --object can not be used together |
| File doesn't exist / is a folder | File '...' does not exist. |
| Jinja syntax error in the template | Template Error: unexpected '}' |
Corrupted .docx template |
Could not load template 't.docx': ... |
Corrupted .xlsx / JSON not a list of objects |
Could not read data file 'data.json': JSON data must be a list of objects |
| JSON template rendered invalid JSON | Template Error: Rendered output is not valid JSON: ... |
--order / --group-by column doesn't exist |
Key 'salary' not found in data, Available keys: name, age |
--filter isn't valid JSON |
Expecting property name enclosed in double quotes: ... |
| Unknown filter rule | Rule 'nope' does not exist. Available rules: is_true, is_null, ... |
| Invalid value for a rule | Argument 'value' with value 'soon' failed to process, ... |
| Filter hit an empty cell or wrong type | Filter failed on a data value (empty cell or wrong type?): ... |
Each extension point is a registry filled with a decorator. Add your code, and the CLI picks it up automatically, including --help and the error messages. Data sources and filter rules live in pyrecords, shared with other CLIs.
pyrecords/readers.py: a function that takes a path and returns a list of dicts, registered on readers. A reader for render --object returns one dict and is registered on object_readers.
import csv


@readers.reader("csv")
def read_csv(filepath: Path) -> Data:
    with filepath.open(encoding="utf-8", newline="") as f:
return list(csv.DictReader(f))src/templify/writers.py: a class built from the template path that implements the Writer protocol, i.e. a write(context, filepath) method.
class Writer(Protocol):
    def write(self, context: Context, filepath: Path) -> None: ...
Text-based formats can simply be added to TextWriter:
@writers.writer("txt", "md", "html", "htm", "xml", "csv")
class TextWriter: ...
A format with its own engine gets its own class:
@writers.writer("pptx")
class PptxWriter:
    def __init__(self, template_path: Path) -> None:
        self.template_path = template_path

    def write(
        self, context: Context, filepath: Path
    ) -> None: ...  # render context into the template and save to filepath
A format that needs validation can extend TextWriter and override render, the way JsonWriter does.
pyrecords/filter_rules.py: the first two parameters are the row and the column. A Process marker on a parameter converts the value coming from the filter JSON.
@rules.rule()
def float__between(d: dict[str, Any], key: str, low: FloatValue, high: FloatValue) -> bool:
    return low <= d[key] <= high
--filter '{"name": "float__between", "args": ["salary", 1200, 1600], "kwargs": {}, "inverse": false}'uv syncRun the tests. Coverage (lines and branches) is printed after every run:
uv run pytestLint and format:
uvx ruff check src testsuvx ruff format src testsThe demo GIFs are recorded with VHS (scoop install vhs
or brew install vhs) and PowerShell (pwsh), from the repository root:
vhs docs/demo/each.tape && vhs docs/demo/schema.tape && vhs docs/demo/schema-list.tapesrc/templify/
├── writers.py # Writer protocol, WriterRegistry, Docx/Text/Json writers,
│ # write_single / write_multiple, file naming
└── cli/
├── main.py # the commands
├── help.py # long --help texts
└── dependencies/
├── data.py # -d, --order, --filter, --group-by pipeline
├── template.py # -t (picks the writer) and -o
└── console.py # rich console
tests/
├── test_writers.py
└── test_cli.py # end-to-end user scenarios
templify is free software, released under the GNU General Public License v3.0 or later (see LICENSE).