Repository navigation
[bug] agent: a turn hangs forever when the provider's first byte exceeds the fixed 120s read timeout #345
Description

Problem
The model gateway applies a hard-coded 120s read timeout to every request (model_gateway.py:127). When a provider takes longer than that to emit its first byte, the gateway returns 502 to the bundled harness, the harness re-sends the same body, and the cycle repeats. The turn never reaches a terminal state: the chat panel keeps showing "thinking", and the only signal is agent.model.error ... failure=ReadTimeout in the server log.
Reproduction without any provider account
A stub endpoint that accepts POST /chat/completions and never responds is enough: slow_provider.py (stdlib only, binds 127.0.0.1:18099, answers GET /v1/models so the connection can be created in Settings).
- Start the stub, add an Agent connection at
http://127.0.0.1:18099/v1with modelslow-model. - Send any message.
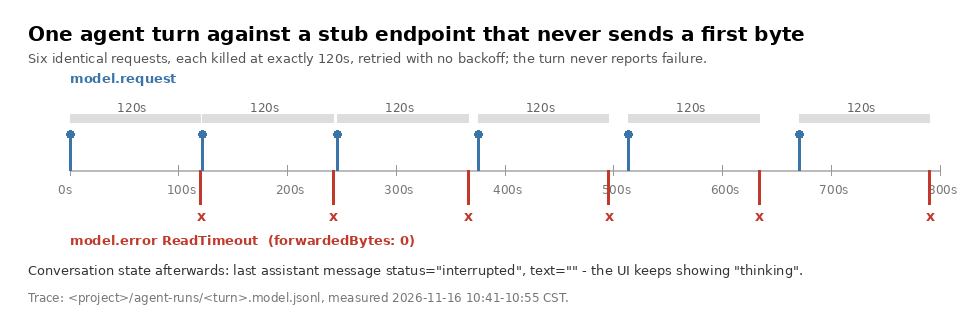
- Six requests go out over 13 minutes, then nothing further is reported.
<project>/agent-runs/<turn>.model.jsonl:
+   0.0s model.request
+ 120.0s model.error    ReadTimeout   forwardedBytes: 0
+ 122.1s model.request
+ 242.2s model.error    ReadTimeout
+ 246.4s model.request
+ 366.4s model.error    ReadTimeout
+ 375.6s model.request
+ 495.6s model.error    ReadTimeout
+ 514.0s model.request
+ 634.0s model.error    ReadTimeout
+ 670.6s model.request
+ 790.6s model.error    ReadTimeout
Stored conversation afterwards:
user      status=complete     text='你好'
assistant status=interrupted  text=''
So the persisted status is already interrupted, and AssistantPanel.tsx:490 renders a label for it, but the panel only picks that up on reload. During the live turn nothing changes, so a slow provider is indistinguishable from a dead one.
Where the retries come from
ModelGateway contains no retry logic; it forwards, traces and returns 502 on failure. The repeats are issued by the bundled OpenCode runtime, whose provider block is assembled in native.py:98-114 and does not set a retry policy, so the AI SDK default applies. Intervals in the trace above are +2.1s, +4.2s, +9.2s, +18.4s, +36.6s, i.e. no meaningful backoff relative to a 120s attempt. Any fix for the retry behaviour belongs in the OPENCODE_CONFIG_CONTENT the gateway builds, not in the gateway's request path.
How reachable is 120s in practice
Identical request body (the system+user pair from a real hung turn, 3 tool definitions, max_tokens: 8192, stream: true), three providers interleaved 12s apart from one host, read timeout raised to 400s so nothing is cut short. 2026-11-16 10:15-10:31 CST, 12 calls each.
| provider | model | ok | first byte min / median / max | failures |
|---|---|---|---|---|
| DeepSeek | deepseek-v4-pro |
12/12 | 0.2 / 0.2 / 0.8s | none |
| Zhipu BigModel | glm-5 |
12/12 | 0.8 / 1.0 / 9.0s | none |
| Moonshot | kimi-k3 |
8/12 | 4.6 / 13.3 / 26.8s | ConnectTimeout x4 |
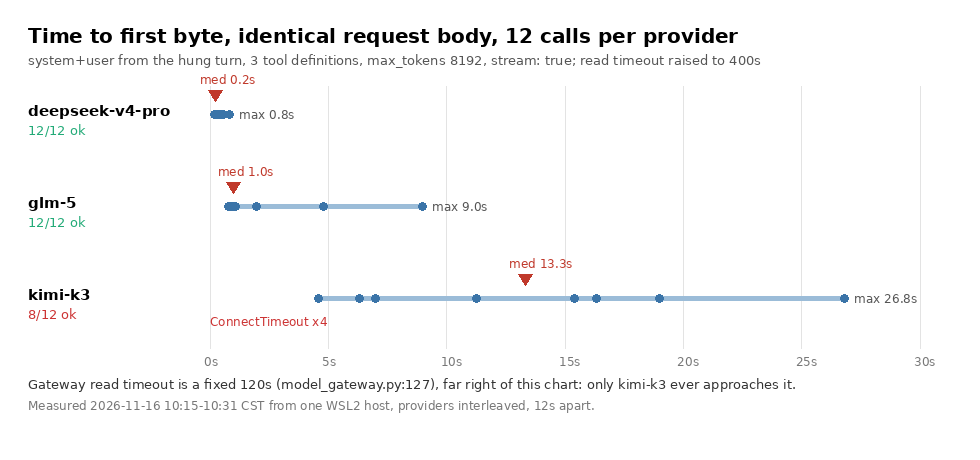
120s is comfortable for DeepSeek and Zhipu. Moonshot is an order of magnitude slower, and in an earlier window the same morning (09:0x CST, 6 calls) the same body returned its first byte after 73.4 / 75.5 / 91.7 / 95.0 / 122.3 / 180.4s — 2 of 6 above the timeout. That window is where the real hang occurred here. The tool definitions are not the cause: dropping tools from the same body in the same window gave 4.2 / 4.4 / 7.5s.
One more case the timeout has to cover: a Moonshot call delivered its first byte at 19.7s and then stalled mid-stream until the 400s read timeout fired. A first-byte-only deadline would not catch that.
I hold keys for these three providers only, so I cannot speak for a self-hosted vLLM, a proxied overseas endpoint, or a long-context reasoning model. The constant itself is provider-independent: ModelGateway is constructed for every runtime == 'default' connection (native.py:223), and no ModelConfig field can override it.
Suggested fix, in order of value per unit of risk
1. Report the failure while the turn is live. This is the defect proper. When the gateway fails with forwardedBytes == 0, end the turn and stream the terminal state to the panel instead of letting the harness silently re-send. The interrupted status and its localized label already exist, so the work is about emitting it at the right moment, and distinguishing a timeout from a user-initiated stop; model.error already carries the exception name.
2. Declare a retry policy for the bundled harness. Set an explicit bounded retry with backoff in the OpenCode config built by command(), rather than inheriting the SDK default. Each silent re-send can re-bill the prompt, and on accounts limited to one concurrent request it collides with the attempt it is replacing.
3. Make the read timeout configurable, keeping 120s as the default. An environment variable such as OPENDIRECTOR_MODEL_READ_TIMEOUT unblocks slow endpoints without changing anyone else's behaviour and avoids guessing a new universal number. It should cover the whole read, not just the first byte, per the mid-stream stall above.
I would not special-case a single provider: measured latency moves (Moonshot's median was ~93s at 09:0x and 13.3s at 10:2x), and ProviderPreset has no field for it today.
Happy to send a PR for whichever subset you want, in that order.
Out of scope
My Moonshot key is limited to 3 RPM and 1 concurrent request, so 22 calls 4s apart produced 8 immediate 429s. That is an account tier, not a defect. Worth noting only because the responses carry no Retry-After header — the hint lives inside the JSON body — which is why unbounded re-sends make the situation worse rather than better.
Environment
WSL2 Ubuntu 24.04.5, Python 3.12.3, origin/main at 16c222e9, dev server started with python3 -m opendirector.cli dev. Chart sources and the stub live on the evidence/model-timeout branch of my fork. No credentials appear in this report or in that branch.
Suggested labels: type:bug, area:agent, area:harness, area:provider.
Activity