
The most advanced MCP memory server. Period.
Hybrid search (BM25 + jina-embeddings-v5 RRF + cross-encoder rerank) · 100+ languages · Temporal Knowledge Graph · Query-aware ranking · Corpus origin detection · Agent/persona disambiguation · Topic tunnels · AAAK compression (5-10x token savings) · GraphRAG · Chunked RAG · Auto-Compaction · Auto-Classification · Memory Capsules · HTTP API · Signed automatic updates · Single binary · Zero API calls






AI coding assistants forget everything between sessions. MemoryPilot gives them persistent, searchable memory with project awareness, semantic understanding, and automatic knowledge organization. Built-in AAAK compression and memory capsules reduce token consumption by 5-10x when loading context. Every memory is auto-classified with the right importance, kind, and TTL on insert. The database compacts itself automatically — zero maintenance.

One-liner install for Cursor, Claude Desktop, VS Code, Windsurf, Claude Code, Codex and ChatGPT. Single Rust binary, zero runtime dependencies. |

The 9 pillars — hybrid search, temporal knowledge graph, GraphRAG, AAAK compression, auto-classification, self-healing — explained end to end. |
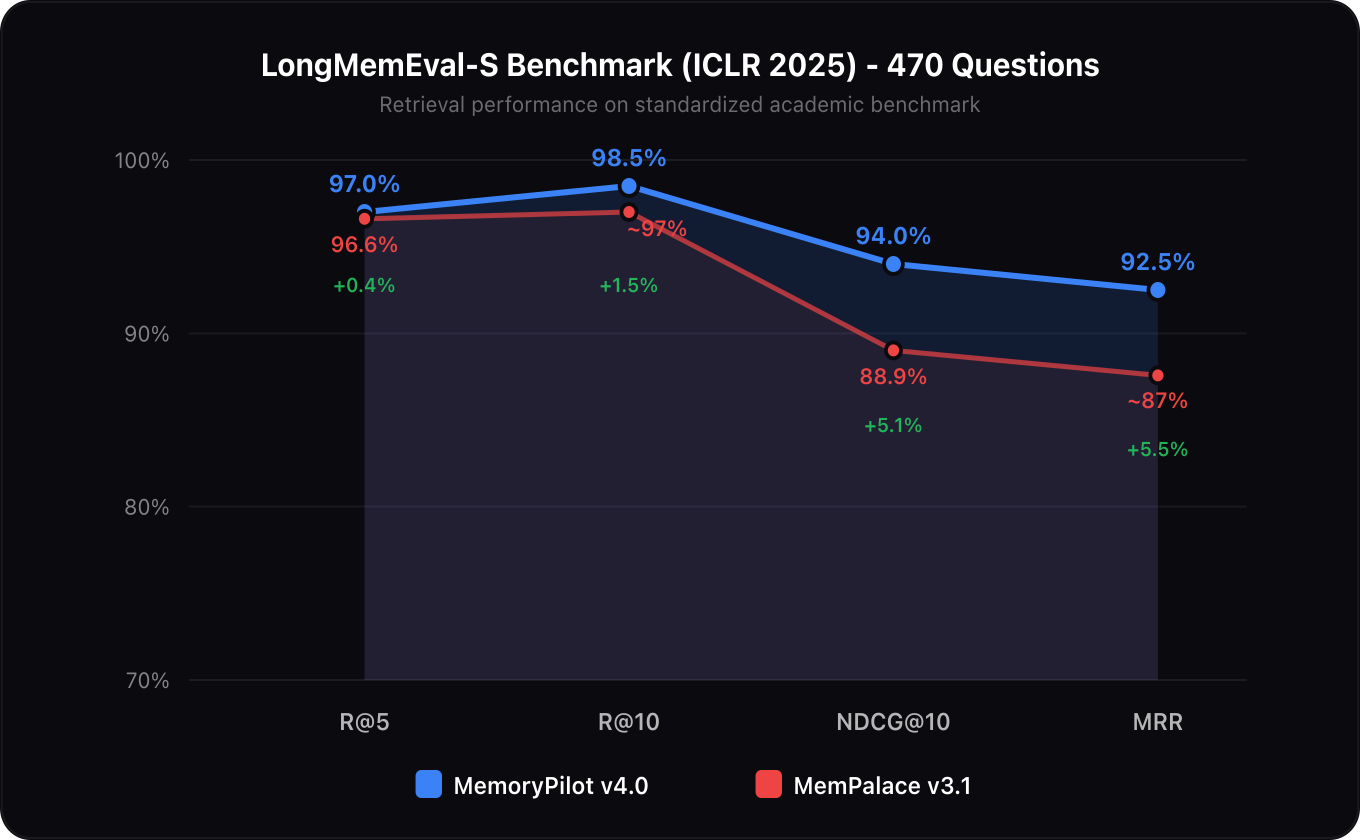
Evaluated on the 470 answerable questions of LongMemEval-S (ICLR 2025; the 30 abstention questions are left out, as the official retrieval protocol does). Turn-level index, ~50 sessions per haystack.
What the score measures. R@5 here is session-level recall_any@5: a question counts as a hit when at least one of the top 5 retrieved turns belongs to one of its gold sessions. It is a retrieval metric, not answer accuracy, and a question that needs several sessions counts as a hit as soon as one of them is found (300 of the 470 questions have more than one gold session). For scale: a plain BM25 over turns, with no embeddings, scores about 93% on the same metric and 74% on recall_all@5. These figures were measured with v4.2 (multilingual-e5-small); the current default model has only been measured on a 100-question slice (see v4.6 below).
| System | R@5 (recall_any, session level) | Notes | Source |
|---|---|---|---|
| MemoryPilot v4.2 (adaptive rerank) | 99.1% | 470 questions, ~900 ms/query on an M-series Mac | This repo, --benchmark-longmemeval |
| MemoryPilot v4.2 (rerank off) | 98.7% | 470 questions, ~28 ms/query with MEMORYPILOT_CROSS_RERANK=off |
This repo, --benchmark-longmemeval |
| MemPalace v3.12.0 (hybrid) | 98.4% | 450 held-out questions after tuning on 50; 96.6% raw on 500 | MemPalace README, read 2026-11-16 |
| ICM v0.11.5 | 97.4% | 500 questions (487 hits), no LLM, one memory per session | rtk-ai/icm README, read 2026-11-16 |
| agentmemory v0.9 | 95.2% | 500 questions (abstention included), all-MiniLM | github.com/rohitg00/agentmemory benchmark/LONGMEMEVAL.md |
| mcp-memory-service v10.34.0 | 80.4% | labelled R@5; hit definition not stated | v10.34.0 release notes |
Answer accuracy (a different metric: an LLM reads the retrieved context and a judge grades the answer)
| System | QA accuracy | Context per question | Setup | Source |
|---|---|---|---|---|
| Recallium (closed) | 98.4% | 12,600 tokens | Claude Opus 5.5 in an agentic harness, gpt-4o judge, whole sessions as the retrieval unit | recallium.ai/benchmarks, read 2026-11-17 |
| MemoryPilot | 97.2% (486/500) | 6,047 tokens | Claude Opus 5.5 as reader, gpt-4o-2024-08-06 judge, one search per question, no LLM call at write time | This repo, benchmarks/results/longmemeval-s |
| Maximem Synap | 95.6% | 7,400 tokens | Gemini 3.8 Flash as reader, gpt-4o judge | maximem.ai/evals, read 2026-11-17 |
| Mastra (observational memory) | 94.87% | not published | see source | mastra.ai research, read 2026-11-17 |
| Hindsight | 94.6% | not published | see source | vectorize-io/hindsight-benchmarks, read 2026-11-17 |
| Mem0 (managed platform) | 94.4% (472/500) | not published | Mem0's own suite, top-200 retrieval; reader and judge not stated on the page | mem0ai/memory-benchmarks, read 2026-11-16 |
| Zep (cloud, 2026) | 90.2% (451/500) | 4,408 tokens (median) | gpt-5.4 as reader and as judge | getzep.com research, read 2026-11-16 |
| Zep / Graphiti (2025 paper) | 63.8% / 71.2% | not published | gpt-4o-mini / gpt-4o as reader, GPT-4o judge | arXiv 2501.13956, Table 2 |
| Supermemory | 85.2% / 84.6% | not published | gemini-3-pro / gpt-5 as reader, LongMemEval-S, 500 questions | supermemory.ai research, read 2026-11-16 |
MemoryPilot's end-to-end run (2026-11-18, compact search as released in v4.14.0). All 500 questions, abstention included. MemoryPilot indexes each haystack turn by turn with no LLM call, answers one search_memory per question, and the 50 turns it returns go to the reader in the official LongMemEval prompt (run_generation.py, chain of thought on). The official judge prompts (evaluate_qa.py) grade the answers with gpt-4o-2024-08-06 at temperature 0. The search is a compact one: assistant turns ranked after the third are cut to 150 characters, which keeps the prompt at 6,047 tokens per question (measured: 3,023,706 prompt tokens over 500 questions).
| Question type | Correct |
|---|---|
| knowledge-update (78) | 76 |
| multi-session (133) | 124 |
| single-session-assistant (56) | 56 |
| single-session-preference (30) | 30 |
| single-session-user (70) | 69 |
| temporal-reasoning (133) | 131 |
| All (500) | 486 (97.2%) |
| of which abstention (30) | 27 |
Every answer and every verdict is in benchmarks/results/longmemeval-s: the run itself (search metrics, the reader's 500 answers, token counts) and the same answers graded by the official judge. The folder also holds an earlier run with the 50 turns returned whole (485/500 at 15,497 tokens per question). The dataset is LongMemEval (MIT). To reproduce, with an API key in MEMORYPILOT_LLM_API_KEY:
MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json --e2e --cot --answer-max-tokens 1500 --context-turns 50 --compact --llm-base-url https://api.anthropic.com/v1 --answer-model claude-opus-5-5 --judge-model claude-haiku-5-5 > run.jsonMemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json --rejudge run.json --llm-base-url https://api.openai.com/v1 > run-gpt4o.jsonLimits of this measure: a single run; the settings (50 turns, cut at 150 characters after rank 3) were chosen on this same question set, not on a held-out split; nobody outside this project has rerun it. The compact mode ships in v4.14.0; the run predates the widening of its candidate pool to 100, which has not been measured end to end.
All figures are published by their own authors, none was reproduced independently, and the two tables cannot be compared with each other. On answer accuracy MemoryPilot is second to Recallium's published score and uses about half its context; on session-level recall MemoryPilot posts the highest published local score, by a margin smaller than the gap between this metric and a plain BM25 baseline. The protocol to settle a comparison: same 470 questions, same hardware, every system run by the same script, reporting
recall_any@5,recall_all@5, turn-level evidence recall and end-to-end QA accuracy with a fixed reader and judge.
Quality is one axis. The others decide what a memory costs on every conversation and every write.
| Measure | MemoryPilot v4.14 | How to reproduce |
|---|---|---|
| LLM calls per write | 0 | Dedup, entities, graph links and embeddings run locally |
| LLM calls per search | 0 | Local encoder and reranker |
| Tools exposed, default profile | 25 | --footprint |
| Tool list, default profile | 23,919 characters, about 6,000 tokens | --footprint (tokens estimated at 4 characters each) |
| Tools exposed, full profile | 74 | MEMORYPILOT_TOOLS=full |
| Tool list, full profile | 45,809 characters, about 11,500 tokens | --footprint |
| Server instructions | 2,736 characters, about 680 tokens | --footprint |
| Runtime dependencies | none | One binary; no database server, no API key |
For scale, as published by each project and read on 2026-11-16: Mem0, Zep, Graphiti, Letta, Supermemory and Hindsight call an LLM on every write; MemPalace does not. Tool counts: Cognee 6 by default, Mem0 11, Zep 12, ICM 32, MemPalace 47. Clients that defer tool schemas (Claude Code does by default) mostly pay for tool names and server instructions, so the count matters less there than on clients that load every schema.
Other long-term-memory benchmarks: ICM publishes 92.9% answer accuracy on LoCoMo (1,540 questions, Gemini as reader and judge, source); Mem0 92.5% and Zep 94.7% on LoCoMo, on their own harnesses. MemoryPilot has no LoCoMo runner yet.
| Metric | MemoryPilot v4.2 (rerank off) | MemoryPilot v4.2 (adaptive rerank) | MemPalace v3.3.3 | Delta vs MemPalace |
|---|---|---|---|---|
| R@5 | 98.7% | 99.1% | 96.6% raw / 98.4% hybrid | +2.5% vs raw / +0.7% vs hybrid |
| R@10 | 99.6% | 99.4% | ~97%¹ | +2.6% vs raw |
| NDCG@10 | 95.1% | 96.0% | Not published | MemoryPilot publishes |
| MRR | 93.6% | 94.9% | Not published | MemoryPilot publishes |
| Avg search latency | ~28 ms (MEMORYPILOT_CROSS_RERANK=off) |
~900 ms (the default) | N/A | search call only, models warm |
¹ Validated with the full 470-question evaluation set (after dropping the 30 abstention questions) in two modes: hybrid retrieval with the rerank off (BM25 + cosine RRF,
MEMORYPILOT_CROSS_RERANK=off, ~28 ms/query) and the default adaptive cross-encoder rerank (MEMORYPILOT_CROSS_RERANK=adaptive, jina-v2-multilingual, fusion weight 0.45, ~900 ms/query, suitable for benchmarks and high-stakes recall). Latencies cover the search call only, with models loaded; MemPalace's figures come from a different question split.
| Category | R@5 | R@10 | MRR |
|---|---|---|---|
| single-session-user (64) | 100% | 100% | 96.6% |
| single-session-assistant (56) | 100% | 100% | 98.8% |
| multi-session (121) | 100% | 100% | 95.7% |
| knowledge-update (72) | 100% | 100% | 98.2% |
| temporal-reasoning (127) | 97.6% | 98.4% | 93.3% |
| single-session-preference (30) | 96.7% | 96.7% | 75.9% |
To complement the English-only LongMemEval, MemoryPilot ships its own deterministic French benchmark covering 109 memories and 109 paraphrased queries across infra, mobile, web, security, and ML domains. The queries are intentionally distant from the indexed wording so they actually exercise the semantic lane.
| Mode | R@5 | R@10 | MRR | Avg latency |
|---|---|---|---|---|
| Default fast (BM25 + jina RRF) | 92.7% | 99.1% | 74.4% | ~100 ms |
| Adaptive cross-encoder rerank, mmarco (v4.10) | 99.1% | 99.1% | 97.4% | ~210 ms (Apple Silicon) |
| Adaptive cross-encoder rerank, jina-reranker-v2 (default since v4.11) | 100% | 100% | 98.0% | ~436 ms (2-vCPU Linux VM) |
v4.5 fixed a ranking bug that had capped this benchmark at R@5 ≈ 70% since v4.0: knowledge-graph neighbours were injected at a hard-coded score (0.1) above every genuine RRF hit (max 2/41 ≈ 0.049), so they occupied the cross-encoder window and pushed real matches past limit. Neighbours now enter below the weakest genuine candidate and only the cross-encoder can promote them.
v4.5.0 also closes two write-path stability bugs surfaced by that work: the episodic rollup embedded every hourly bucket on each pass (before checking whether the episode already existed) and did so synchronously inside add_memory, then panicked on multi-byte French text; it now runs on its own thread with a cheap existence check first. And auto-compaction held a Mutex across run_gc/compact_to_capsules, whose merged rows re-enter add_memory — a deadlock hidden until the rollup stopped panicking ahead of it.
Run-to-run variance is bounded to ±1 pp on R@5 / R@10 thanks to deterministic memory ids, deterministic id-based RRF tie-break, synchronous ANN warm-up, and explicit cross-encoder pre-warm before the first query. This is the metric to watch for any French / multilingual regression.
v4.6.0 targets the LongMemEval categories a top-k retriever alone cannot win: multi-session aggregation, temporal reasoning, knowledge updates and abstention. Everything stays local and rule-based or int8 ONNX. Measured on LongMemEval-S@100 (64 single-session + 36 multi-session, plus the 7 abstention questions of that slice) against v4.5.0, same machine, cross-encoder adaptive:
| Metric | v4.5.0 | v4.6.0 |
|---|---|---|
| R@5 / R@10 | 99% / 100% | 100% / 100% |
| MRR / nDCG@10 | 96.3% / 97.2% | 96.5% / 97.3% |
| Multi-session gold coverage@10 | 93.6% | 94.5% |
| Multi-session questions with all gold sessions in top-10 | 30/36 | 32/36 |
| False abstention on answerable questions | — | 4% |
Extractive answer (search_memory … answer=true), contains-gold |
— | 48% (72% single-session; counting questions are out of reach for span extraction) |
--benchmark-fr is unchanged within noise (R@1 96.3%, R@5 99.1%, MRR 97.6%).
- MMR diversity (
src/diversity.rs) — the finalists plus the RRF ranks just below them are re-ordered by maximal marginal relevance over their stored vectors (λ = 0.4, redundancy floor 0.55). The top hit never moves, so MRR is untouched; a second, distinct source can displace a restatement of the first.MEMORYPILOT_MMR=0disables it. - Temporal grounding (
src/temporal.rs) — explicit dates in a memory (2026-09-01,12 septembre 2026,September 12,hier…) becomedateentities at ingest; a temporal phrase in the query (last week,il y a deux semaines,en mars,last Tuesday) becomes a day window that boosts dated candidates inside it (×1.25) and mildly demotes dated candidates far outside (×0.85). Undated memories are neutral, so a mis-parsed window costs at most the boost.MEMORYPILOT_TEMPORAL=0disables it. - Contextual embeddings — transcript chunks and other context-poor kinds are embedded with a
[date · project]prefix while the stored content and its hash are left untouched. - Superseding — the daily consolidation pass links a memory to a newer, near-identical restatement with a changed value (cosine ≥ 0.86, lexical overlap 0.55–0.95, ≥ 1 h apart) and the old one is demoted (−0.35) at search time. Both stay retrievable;
consolidate_memories(apply=true)reports the links made. - Calibrated confidence — every search returns
confidence: { top_cosine, peak, cross_score, margin, level, abstain }. On LongMemEval the abstention haystacks are built from the same user's other sessions and no cheap signal separates them from answerable questions (top-1 cosine p50 0.46 vs 0.54, cross-encoder logits overlap fully), so the hardabstainis deliberately conservative (cosine < 0.35, 4% false abstention) andlevelcarries the graded signal.MEMORYPILOT_ABSTAIN_COSINEmoves the floor. - Extractive reader (
src/reader.rs, opt-in) —search_memorywithanswer: truerunsdeepset/roberta-base-squad2(int8 ONNX, 125 MB, English, loaded on demand through the idle pool) over the top-5 passages and returns the literal span or nothing. ~480 ms per question on CPU. It is a benchmarking instrument and a shortcut for literal lookups, not a language model: it abstained on 5/7 LongMemEval abstention questions where the retriever could not.--benchmark-longmemeval --readerreports SQuAD-style EM / F1 / contains.
| Metric | MemoryPilot v4.2 | MemPalace v3.1 (raw) | Quantum Memory Graph |
|---|---|---|---|
| R@5 | 100% | 96.6% | 93.4% |
| R@10 | 100% | N/A | 93.4% |
| NDCG@10 | 95.6% | 88.9% | 90.8% |
| Cluster Coherence | 96.7% | N/A | N/A |
| Multilingual | 100+ languages (validated FR R@5 99.1%) | English only | English only |
| AAAK Compression | 5-10x (no recall loss) | 30x (recall drops to 84.2%) | N/A |
| Avg Search Latency | ~28 ms rerank off / ~410 ms adaptive (default) | N/A | ~80 ms |
| Install size | 35 MB binary + ~530 MB of models downloaded on first run | ~500 MB (Python+ChromaDB) | 1.5 GB |
| Dependencies | none at runtime (single binary, ONNX bundled; models fetched from Hugging Face once) | Python + ChromaDB + SQLite | Python + ONNX |
vs the best memory servers on the market:
| Feature | MemoryPilot v4.7 | MemPalace v3.3.3 | agentmemory v0.9 | Mem0 | Zep / Graphiti |
|---|---|---|---|---|---|
| LongMemEval | 99.1% R@5 (v4.2, recall_any) | 98.4% R@5 (held-out split) | 95.2% R@5 | 94.4% QA accuracy (not comparable) | 63.8% QA accuracy (not comparable) |
| LongMemEval MRR | 94.9% | not published | 88.2% | not published | not published |
| Search | Hybrid BM25 + jina-embeddings-v5-nano RRF (768-dim, int8) + adaptive multilingual-reranker-small cross-encoder | ChromaDB cosine (all-MiniLM-L6-v2) | BM25 + vector + graph (RRF) | Vector search (cloud API) | Temporal KG traversal + vector |
| Embeddings | jina-embeddings-v5-text-nano-retrieval (100+ languages, 8k context, local ONNX) | all-MiniLM-L6-v2 (English only) | all-MiniLM-L6-v2 (English only) | OpenAI API calls (external) | OpenAI / cloud LLM extraction |
| Multilingual | 100+ languages native (FR, EN, ES, DE, JA, ZH...) | English only | English only | Depends on API | Depends on LLM backend |
| Knowledge Graph | Temporal triples with validity + confidence | Temporal triples (SQLite) | Knowledge graph (no validity window) | Basic graph (no temporal) | Temporal KG (Graphiti, core feature) |
| GraphRAG | Auto entity extraction + graph traversal + combinatorial reranker | No | Partial (graph search lane) | No | Yes (LLM-based extraction) |
| Cross-encoder rerank | multilingual-reranker-small (adaptive) | No | No | No | No |
| Query-aware ranking | Preference/temporal/role/update/technical intent boosts | Hybrid v4 keyword + temporal boosts | RRF fusion only | Depends on API | Graph-distance scoring |
| Corpus origin detection | AI transcript/codebase/notes/platform detection | v3.3.4 prep | No | No | No |
| Agent/persona disambiguation | Agents are separate from real people | v3.3.4 prep | Hooks-based session scoping | No | Partial (entity nodes) |
| Topic tunnels | Cross-project topic links via KG | v3.3.4 prep | No | No | No |
| Code-aware chunking | Tree-sitter Rust/Python/TS/TSX/JS + Svelte script extraction | Tree-sitter code chunking | No | No | No |
| Chunked RAG | Transcript auto-chunking + auto-distillation (8 types) | Conversation chunking by exchange | Session replay + JSONL import | No | LLM-based summarisation |
| Compression | AAAK + Memory Capsules (5-10x token savings) | AAAK dialect (experimental, regresses recall to 84.2%) | 4-tier consolidation + decay | No | No |
| Auto-Classification | Zero-shot kind/importance/TTL on insert | No | Pattern-based via hooks | No | LLM-classified entities |
| Auto-Compaction | GC triggers automatically at 500+ memories | No | Lifecycle decay + auto-forget | No | Manual |
| Memory Capsules | Compress old memories into dense summaries | No | Tier-based consolidation | No | No |
| Memory Pinning | Pin critical memories — always in recall, GC-proof | No | No | No | No |
| Graph Traversal | Find related memories via KG (depth 1-3) | No | Yes (graph lane) | No | Native (Cypher / Neo4j) |
| Bulk Operations | Delete by kind/project/tag/age with safety guards | No | Governance delete API | No | Manual |
| Health Dashboard | Memory distribution, stale count, orphans, DB size | No | Real-time web viewer (port 3113) | No | No |
| Dedup Detection | Jaccard similarity scan for near-duplicates | No | Not documented | No | LLM-based reconciliation |
| Person detection | Auto-detects team members from text | No | No | No | LLM-extracted entities |
| Self-Healing | Background auto-linting loop | No | No | No | No |
| Garbage collection | Heuristic merge + scoring + orphan cleanup | No | Lifecycle + decay | Basic TTL | No automatic GC |
| Project brain | Yes, with team members (<1500 tokens) | No | Session summary on demand | No | No |
| File watcher | Context boost from recent edits | No | Filesystem connector (@agentmemory/fs-watcher) |
No | No |
| Deduplication | Content hash (exact) + Jaccard 85% (fuzzy) | Basic hash | Confidence scoring | Embedding similarity | LLM-based merge |
| HTTP API | Multi-threaded REST server (optional) | No | REST + MCP + leases + signals | Cloud hosted | REST + GraphQL |
| Memory types | 15 types, importance 1-5 | Wings/Rooms hierarchy | Tier-based (working / short / long / archival) | 1 type | Episodic / semantic |
| MCP tools | 74 tools, 25 exposed by default (the rest behind memory_admin) |
47 tools | 65 tools | N/A | Limited MCP server |
| Hooks / event capture | SessionStart auto-recall for Cursor, Claude Code and Codex, per-prompt recall (Claude Code), conversation index at session end, opt-in Stop auto-ingest (incremental, distilled, agent narration filtered, secrets redacted) + file watcher | No | 12 named hooks (Claude Code, Cursor, Codex, Copilot CLI…) | No | No |
| Privacy | 100% local, zero API calls | 100% local | 100% local (SQLite) | Cloud dependent | Cloud or self-host (LLM required) |
| Language | Rust (single binary, zero deps) | Python (pip install) | TypeScript / Node (npm install) | SaaS | Python + Neo4j |
| Startup | 1-2 ms (open_at) / synchronous warm via open_at_warm |
~5 ms | Node boot + iii-engine init | N/A (cloud) | Heavy (Neo4j boot) |
| Binary | 35 MB single binary | Python + ChromaDB (~500 MB installed) | Node runtime + iii-engine deps | SaaS | Python + Neo4j (~1.5 GB) |
| Storage | SQLite WAL + FTS5 + 16-conn read pool | ChromaDB | SQLite + iii-engine | Cloud DB | Neo4j + Postgres |
| Concurrency | EmbedPool (4) + RerankPool (1, tunable) + 16 read conns + debounced cleanup | Single-threaded | Node event loop | Single-threaded | Neo4j-bound |
| External LLM dependency | None | None | None (local embeddings) | OpenAI required | LLM required for ingestion |
| GitHub stars (Sept 2026) | nascent | nascent | ~28.9k | 53k | — |
Every memory gets a 768-dimension transformer embedding on insert via ONNX Runtime (jina-embeddings-v5-text-nano-retrieval, int8, local inference — 100+ languages including French, English, Spanish, German, Japanese, Chinese — no API calls, no external services; the model is fetched from its Hugging Face repository on first run, licence CC-BY-NC-4.0). Queries and documents use the model's asymmetric Query: / Document: prefixes. The int8 weights are memory-mapped, so the embedder costs ~250 MB resident, most of it reclaimable file-backed pages. Search runs both BM25 full-text and cosine similarity in parallel, then merges results with Reciprocal Rank Fusion.
Results are boosted by importance weighting, knowledge graph link density, file watcher context, and penalized for expired knowledge triples.
Ephemeral working memory is available in the same MCP through remember_working, recall_working, and clear_working. It keeps fast session scratchpad context in RAM, capped to 256 items, without polluting SQLite or durable recall.
Performance optimizations:
- Lazy embedding:
add_memoryreturns instantly, embeddings computed in background thread - Two-tier query embedding cache (LRU 256 + write-through SQLite): repeated queries skip ONNX inference
- Read connection pool (16 connections): concurrent vector searches don't block writes, sized for HTTP server workloads
- EmbedPool (4 sessions, env-tunable): parallel embeddings without serialization on a single ONNX mutex
- RerankPool (1 session, env-tunable to 2): parallel cross-encoder rerank under multi-client load
- Content hashing (FNV-1a): backfill skips unchanged memories
- Synchronous warm-up entrypoint
open_at_warm: hydrates the ANN index in RAM before returning, eliminating cold-start tail (p95 search latency 3939 ms → 229 ms in the 4-client concurrency bench)
A full knowledge graph with temporal validity. Facts have valid_from / valid_to dates and confidence scores. When facts become outdated, they are invalidated rather than deleted — giving the AI a timeline of how knowledge evolved.
Entities (technologies, files, components, people) are automatically extracted from memory content and linked bidirectionally. Search results from memories with all-expired triples are penalized.
5 dedicated KG tools: kg_add, kg_invalidate, kg_query, kg_timeline, kg_stats
Every memory is automatically analyzed for entities: technologies, file paths, components, projects, and people. Entities are stored in a dedicated table. Memories sharing entities are auto-linked with inferred relationship types (resolves, implements, depends_on, deprecates...).
When searching, MemoryPilot traverses the knowledge graph from the top matches to pull in related context — e.g., finding the architecture decision that led to a specific bug fix. A combinatorial reranker then selects the best cluster of connected memories rather than independent top-K results, producing cohesive context (94% cluster coherence). Tuned RRF fusion (k=40), exact term coverage boost, smart FTS tokenization, query-time KG expansion, temporal recency, and importance tiebreakers push NDCG@10 to 94% with perfect R@5/R@10.
Save full conversation transcripts without polluting the LLM context window. The add_transcript tool automatically chunks large texts into ~2000 character blocks and links them together. Chunks are excluded from recall but fully searchable.
For source code, MemoryPilot uses local tree-sitter parsing by default for Rust, Python, TypeScript, TSX, and JavaScript, with Svelte support via <script> extraction plus markup chunking. Code is split on semantic boundaries such as functions, classes, impl blocks, interfaces, and exports instead of arbitrary paragraphs.
Auto-distillation extracts structured memories from transcripts: decision, preference, todo, bug, milestone, problem, and note. Smart disambiguation: a segment mentioning both a bug and its resolution is classified as milestone, not bug.
Supports session_id, thread_id, window_id for multi-window memory scoping.
Inspired by MemPalace's symbolic memory language. When compact: true is passed to recall or get_project_brain, output is compressed ~3x using a terse, pipe-separated format:
[DEC:5] Use Clerk over Auth0 | tags:auth,stack | proj:MyApp
[PREF:4] Always use TypeScript strict mode | tags:typescript
MemoryPilot watches your files. When you save a Rust, Svelte, or TypeScript file, it lints in the background. Compilation errors are automatically stored as bug memories with the exact stack trace. When the error is fixed, the memory is auto-deleted.
The linter thread reuses a single DB connection for its entire lifetime.
Old, low-importance memories are scored for cleanup candidacy. Groups of related stale memories are merged into condensed summaries using heuristic keyword extraction. Orphaned links and entities are cleaned. DB is vacuumed after significant deletions.
Auto-compaction triggers automatically when the memory count exceeds 500: the GC runs in the background after add_memory, debounced to once per 5 minutes. Zero manual intervention.
Memory Capsules (compact_memories tool): compress old low-importance memories into dense ~100-200 token capsules. Credentials and architecture decisions are never compressed. Capsules preserve Knowledge Graph links, giving you 5-10x token savings on aged memories without recall loss.
Every memory is automatically classified on insert when the caller doesn't specify kind or importance. Pattern-based heuristics detect:
- Credentials (API keys, secrets) → importance 5, no TTL
- Architecture decisions → importance 5
- Preferences/patterns → importance 4
- Bugs → importance 3, TTL 90 days
- TODOs → importance 2, TTL 30 days
- Code snippets → importance 2
- Milestones → importance 4
No LLM needed — pure regex + keyword heuristics. The AI can still override by passing explicit kind and importance.
One tool call returns a dense JSON snapshot of a project under 1500 tokens: tech stack, architecture decisions, active bugs, recent changes, key components, and team members (auto-detected person entities). Supports compact: true for AAAK compression.
- Compact search (
search_memorywithcompact: true): the same ranking in a short context. Assistant turns ranked after the third are cut to 150 characters, unless the question is about what the assistant said; a total or a timeline reaches further. The reranker reads 64 candidates out of a pool of 100, whatever the limit. This is the mode behind the LongMemEval-S result above: 97.2% (486/500) at 6,047 prompt tokens per question. - One reranker, served from this repository: multilingual-reranker-small replaces the previous one; its download and loading are more robust.
- Conversation finder: a turn keeps its drafts, its actions and its whole texts; a question in French finds a text written in English, and the reverse;
search_in_conversationsearches inside one conversation; the running conversation no longer shows up in its own search; the index says what it may be missing; a message that Cursor stores under several identifiers is indexed once. A memory keeps the conversation it comes from. - Projects: a project is identified by its git remote, worktrees are attached to it, and a name alias leads to the same project.
merge_projects,rename_projectand theprojectfield ofupdate_memory, with a backup of the database before any merge or rename.get_memory_healthreports duplicate and orphan projects. - Secrets no longer hide a note: a note that holds a secret keeps its kind and its text, and only the value is masked (
[secret masqué : …]); the answer ofadd_memorysays so. The value is not kept: it belongs in a secret manager. Only an explicitcredentialgoes to the vault. File names, version tags and code identifiers are no longer taken for secret values. - Tool annotations: each of the 74 tools states its title and whether it reads, adds or changes data (
readOnlyHint,destructiveHint), so a client can ask for confirmation where it matters. - Memory kinds: requests sent to a third party have their own kind and a waiting list; an absence that was not confirmed is no longer stored as a fact; a kind chosen by the caller no longer receives an automatic expiry.
- Skills: third-party skills are imported and updated after review, with a trust list for updates without review.
--footprint: what MemoryPilot costs a client before any call (tools, characters, instructions).- Benchmark tooling: end-to-end LongMemEval with an LLM judge (
--e2e), evidence coverage at several depths without any LLM call, re-grading of saved answers by another judge (--rejudge). - Fixes: a first start on a new database no longer fails with "database is locked"; the description of
memory_adminfits the 4,096-character limit of clients; rustix moved to its patched release (RUSTSEC-2026-0486). - Known advisory, not fixed in this release: the bundled SQLite (3.45, through rusqlite 0.31) is affected by CVE-2026-119375, which needs a crafted database and
-walpair written by another party into MemoryPilot's data directory. The fix is rusqlite 0.41 or later, a breaking upgrade planned for the next release.
- Conversation finder (
find_conversation,read_conversation): "the Gina comparison for MemoryPilot sorting" finds the conversation where it happened, whichever tool it was in. The index lives in its own database (~/.MemoryPilot/conversations.db, never mixed with memories), is read-only on the sources, and syncs incrementally (a few seconds at most, before a search). It keeps each request, the final answer of each turn, what the agent wrote at length on the way (a draft, a plan) and the actions of the turn (commands run, pages opened), whole, not its short progress notes: 703 conversations, 26,000 messages and 110 MB (vectors included) for 120 GB of Cursor history. On 22 real questions asked from memory, the right conversation comes first for 77% of them and in the top 3 for all of them (MRR 0.87, 150 ms median); words alone reach 91% in the top 3 in 26 ms.--index-conversations(with--rebuildto read every conversation again from its source, as after an upgrade that indexes more),--find-conversation "<query>",--benchmark-conversations <file>. A question in French finds a message written in English, and the reverse, by a lane of translated words (a French and English lexicon of everyday and product vocabulary). The index also says what it may be missing (coverage_warnings: a sync that failed, a session seen running but never read, weeks of silence inside a long conversation), and a turn where the agent typed text on a site known for requests (a vendor's developer forum, a feedback form; more with theexternal_hostssetting) is recorded as an external request to confirm.
- Automatic updates: a running server installs new releases by itself and switches to them in place when idle, without restarting the IDE. Signed manifest, checksum, Developer ID check on macOS, database backup and a self-test of the new binary before anything is replaced; a version that fails to start three times is rolled back. Progressive rollout,
MemoryPilot update [--check],MEMORYPILOT_AUTO_UPDATE=0to turn it off. See Automatic updates. - Rerank fusion weight 0.6 (was 0.45): best R@1 and MRR on a 119-question LongMemEval-S sample (R@1 93.3% to 94.1%, MRR 95.6% to 96.1%), French benchmark R@1 96.3% to 97.2%, average search latency within run-to-run noise (703 ms and 724 ms). A non-numeric or non-finite
MEMORYPILOT_CROSS_RERANK_WEIGHTnow falls back to the default instead of producing NaN scores. --benchmark-longmemevalreports R@1 and recall_all@5 (every gold session in the top 5).- Security updates: h2 (unbounded empty DATA frames), bundled root certificates (distrusted emSign intermediates), crossbeam-epoch, tokio, cxx, rustls, rustls-webpki and openssl moved to their patched releases.
-
Jina models only, non-commercial use: jina-embeddings-v5-text-nano-retrieval and jina-reranker-v2-base-multilingual are the only models (the e5, bge, gte and mmarco options are gone). Both are CC-BY-NC-4.0: see Models: non-commercial use only.
-
Fixes from the October 2026 audit (each one has a regression test in
crates/memorypilot-core/src/db/audit_tests.rs):- A search with
limitof 25 or more (31 on temporal queries) panicked and stopped the process; the limit is now capped at 100 for every interface. - Credentials: the password of a connection URI (
postgres://user:password@host) is masked, and such a URI in a note makes it a credential. SQLite now seals a credential before writing it (no clear text in the table, the FTS index or the WAL) and refuses the write when the vault key is unavailable, unlessMEMORYPILOT_VAULT=off. Entities come from the masked label, soget_project_brainnever returns a secret. A one-shot startup migration repairs databases written by older versions. - Deduplication: a near-duplicate that corrects a figure or a date ("30 jours" then "60 jours") now replaces the old text instead of being dropped; the replaced text is kept in
metadata.previous_versions. - Compaction never touches pinned memories, and every original that
run_gc,compact_memoriesor consolidation removes is kept whole in an archive:list_archivedandrestore_memorybring it back. - An embedding computed for a text edited in the meantime is no longer stored.
- Episodes are built per project (they used to mix every project of an hour), are rebuilt when a source memory changes, disappear with a deleted one, and never include credentials.
- Filtered searches no longer depend on the global ANN top 200, which could miss a small project's best matches past 5,000 vectors.
- The Cursor hook ingests a long transcript backlog in chunks instead of keeping only its last 400 KB.
- Exports include every memory (they stopped at 10,000).
- A search with
-
Memories checked against Git: a memory that cites files of its project's repository is compared with the commits made after it. Search, recall and get add a
verificationobject when there is something to say:likely_resolved(a later fix commit touches the files a bug cites),possibly_resolved(a later fix commit reads like the bug's resolution),changed_since(the cited files changed), or the recordedresolved/verified. Mass commits (over 40 files) and docs, tests or chores are ignored. Git is read on demand and cached per HEAD: nothing is copied into the database.verify_memorygives the detail,resolve_memoryrecords open / resolved / verified with the fixing commit; resolved bugs leave the project brain.MEMORYPILOT_VERIFY=offturns it off. -
Facts read from the repository:
project_factsreturns what the project's repository says about itself right now, computed on demand and never stored: package manifests and versions (package.json,Cargo.toml,pubspec.yaml), Cloudflare config (wrangler.toml/.jsonc, variable names only), cf-orchestrator deploy targets, Supabase migrations, SvelteKit routes, last commit. Recall (project_facts) and the project brain (derived_facts) carry a few-line summary. A memory that states an older framework version than the repository uses ("Tailwind 3" whenpackage.jsonhas^4.1.0) is markedcontradicted; newer versions are read as plans, not stale facts. -
Connectors: GitHub, deploys, Supabase production:
project_factsadds open and recently merged pull requests and open issues (gh, already logged in), the last successful cf-orchestrator deploy of each target with the commits made since in its directory, the latest Git tag with the commits since, and, when a Supabase access token is available, the migrations ofsupabase/migrationsnot yet applied in production (Management API, scopedatabase:read; token fromSUPABASE_ACCESS_TOKENor the Keychain, serviceMemoryPilot, accountsupabase-access-token, passed to curl on stdin, never on the command line). Recall reads a cached copy refreshed in the background every 5 minutes, so it never waits on the network. A bug memory that cites a pull request or issue merged or closed after it was written is markedlikely_resolved.MEMORYPILOT_CONNECTORS=offturns them off. -
Secrets as pointers: no tool returns the value of a credential any more,
fullmode and exports included. A credential comes out as its masked label plus asecretpointer: where the value lives (thelocationset withupdate_memory, anop://reference in the label, or the vault) and how to ask for it.reveal_secret {id, reason}is the only way to the value: the user confirms in a macOS dialog an agent cannot click (Reveal / Refuse, 55 s), and every request is logged to~/.MemoryPilot/logs/reveal-audit.logwithout the value. Updates can no longer destroy a secret: writing back the masked text, replacing the metadata, or changing the kind alone is refused or keeps the ciphertext.MEMORYPILOT_REVEAL_CONFIRM=noneskips the dialog (audit only);MEMORYPILOT_SECRETS=revealrestores transparent decryption; over HTTPreveal_secretis refused unlessMEMORYPILOT_HTTP_SECRETS=on. -
1Password as the home of secrets:
MemoryPilot --sync-1password [--apply]backs up the vault key to 1Password (item "MemoryPilot vault key"), then points every credential to anop://reference: an existing item about the same account (title or URL host in the text) that already holds the value is linked, otherwise a Login or Secure Note is created (tagmemorypilot-import). Nothing is deleted; dry run by default.reveal_secretthen reads the value from 1Password first (op-sofwhen installed, elseop; values only on stdin/stdout) and says where it came from. -
memorypilot-corelibrary: storage, search, recall, knowledge graph and vault now live incrates/memorypilot-core(Cargo workspace); theMemoryPilotbinary is the MCP server on top of it.db.rsis split into one file per domain. Memory rows go through aMemoryStoretrait and everything search and recall read through aRecallStoretrait (SQLite today), with contract tests any other store must pass (store-contractfeature). Same tests, same benchmark results (scripts/bench-gate.sh). -
Server mode, storage (in progress, not part of the release binaries):
crates/memorypilot-serverstores memories for many customers in one Postgres database (full text withtsvector, vectors with pgvector). Tenant, space and end user are isolated twice: every query filters by them, and row level security rejects any row of another tenant. It passes the same store contracts as SQLite, and the write path (dedup, entity and date extraction, links) and the hybrid search pipeline run unchanged on either store: on the French benchmark, Postgres scores recall@10 100% and MRR 97.9% (SQLite: 100% and 98.1%), missing first place on the same three queries. End users link their memories only to what they can see. Connections to Postgres require TLS with the certificate and host name verified (Mozilla roots plus an optional CA file, such as Supabase's), or are explicitly plain for a local or private database. Thememorypilot-serverbinary serves a REST API (/v1/memories,/v1/search) over pooled sessions, authenticated by per-app API keys (read,write,subjects; only their SHA-256 is stored, revocation takes effect at once); withX-MemoryPilot-Subjectan app acts for one of its end users, created on first use, who changes only their own memories. The same keys open an MCP endpoint (POST /mcp, Streamable HTTP) with six memory tools; it serves both the current stateless protocol revision (2026-07-28, version and headers checked on every request) and clients still oninitialize(2025-03-26 to 2025-11-25). Each key has a request rate (600 per minute by default, 429 with Retry-After beyond) and each tenant a memory quota (100,000 by default), both adjustable per tenant. Usage (requests, writes, searches) is counted per space and day for billing, and every change is written to an audit log by id only, which the application role can add to but never read. For GDPR, an app exports an end user's own memories and facts (GET /v1/subject/export) or erases that end user with everything they own (DELETE /v1/subject); both are audited and never create an end user. A leaving customer's data is exported as JSON lines (export-tenant) and deleted only with the tenant's exact name (delete-tenant). Vectors are computed in the background, one batch per tenant in turn, so a memory is found by keywords at once and by meaning a moment later. Large scopes (5,000 vectors and up) find nearest neighbours through a pgvector HNSW index of the model's dimension (384, 768 or 1024), with an iterative scan so a tenant filter cannot empty the results. Credentials are sealed with a key unique to the tenant, itself wrapped byMEMORYPILOT_MASTER_KEY(envelope encryption); reads and exports return the masked label only. The Docker image (Dockerfile,docker compose up --build) bakes the jina embedding model and serves on port 8080. REST clients live insdks/(TypeScript, Python, Dart; not published). MCP clients (claude.ai, ChatGPT) connect with OAuth 2.1: PKCE S256, dynamic registration, onempt_token per end user after pasting an API key on/oauth/authorize. SetMEMORYPILOT_PUBLIC_URLto the public origin. The SvelteKit console (console/, served at/console) signs in with an API key. How to wire Claude, ChatGPT, iPhone, Slate, LightFrame and Docix:integrations/. Server benches without an LLM:scripts/bench-server.sh. Its admin commands create tenants, spaces and keys (memorypilot-server help).scripts/test-postgres.shruns its tests against a local pgvector container. -
No Keychain prompts: the server reads the vault key only when it holds credentials, on a background thread (a prompt no longer freezes every request). The macOS release is signed and notarized, Homebrew installs it on Apple Silicon, and
install.shchecks the checksum and the signing team. -
Vault key safety and recovery: a refused Keychain read no longer creates a new key (only a missing item does).
--restore-vault-keyputs back a key read on stdin after checking it opens every sealed credential;--reseal-recovered [--apply]re-encrypts with the current key credentials recovered in clear (JSON on stdin), each checked against its stored label, all or nothing.
- Outdated memories hidden automatically: when a newer memory says "X instead of Y" about an older one, or is a newer status of the same thing, the older one is tagged
superseded(kept, readable by id,unsupersedeto undo) and no longer surfaces in recall or search. - Better recall: the memories matching the current task come first and are always reranked by the cross-encoder. Recall golden set: top-1 73% → 82%, top-5 91% → 100%, cross-project leak 9% → 0%.
- Index repair at startup (
repair_index), andMemoryPilot --seal-backup FILE...to encrypt credentials inside old backups.
- Project isolation in recall: memories from another project only surface when they name the current one (cross-project leak 55% → 18%, hit rates unchanged).
- Lean tool list: 17 core tools (~13 KB of schema per conversation instead of ~24 KB); everything else through
memory_admin.MEMORYPILOT_TOOLS=fullrestores the full list. - Credentials encrypted at rest: XChaCha20-Poly1305, key in the macOS Keychain (key file elsewhere), masked over HTTP (masked everywhere since v4.11, see secrets as pointers).
archive_transcripts: old raw transcripts move to~/.MemoryPilot/archive/*.jsonland out of the live index.find_conflicts: report of same-project memories that contradict each other.rate_skill: usage feedback on learned skills; reliable ones rank first, failing ones are demoted.- Remote access:
--httpnow requires a token (~/.MemoryPilot/config/http.token), asAuthorization: Beareror/mcp/<token>.scripts/remote-access.shsets up a LaunchAgent and a Cloudflare tunnel so claude.ai, the iPhone app or another PC can use the same memory.
brew install Soflutionltd/memorypilot/memorypilotThat's it. On Apple Silicon, Homebrew installs the signed and notarized release binary (from the first signed release on); Intel Macs and Linux build from source via cargo (Homebrew pulls Rust automatically). After install, run ./install.sh from the cloned repo or follow the manual MCP config below.
Why signed matters on macOS. Credentials stored in MemoryPilot are encrypted with a key kept in your Keychain. macOS lets a binary read it without asking only when that binary is signed by the team that created the key. The signed release keeps that identity across updates, so you are never prompted; a binary built from source (
cargo install, Homebrew on Intel) has a new identity at each build, and macOS asks for your Keychain password after each update. Without stored credentials, the Keychain is never read.
curl -fsSL https://raw.githubusercontent.com/Soflutionltd/MemoryPilot/main/install.sh | bashWhat this does:
- Detects your platform (macOS arm64 / x64, Linux x64 / arm64).
- Fetches the pre-built binary from the latest GitHub Release and checks its
.sha256. - On macOS, checks the signature: refuses a binary signed by another team, warns when it is unsigned.
- Installs to
~/.local/bin/MemoryPilotand clears Gatekeeper attributes on macOS. - Auto-configures every supported IDE / agent it finds — Cursor, Claude Desktop, Claude Code, Codex CLI, Gemini CLI, Windsurf, VS Code, OpenCode, Cline, Roo Code — in a single pass.
If no pre-built binary is available for your platform, it falls back to cargo build --release --features http automatically (requires Rust).
A running server (stdio or --http) looks for a new release 2 minutes after it starts, then every 6 hours. Apart from the first model download, this is the only network call MemoryPilot makes on its own: two small HTTPS requests to github.com for the release manifest and its signature, carrying no identifier, then the archive when there is a new version. When there is one:
- The manifest must carry a valid minisign signature from the key compiled into the binary, and the archive must match the SHA-256 the manifest lists. On macOS the new binary must also be signed by Developer ID team
TB8CC687M3, and on every platform it must answer--versionwith the expected version. - The database is copied (
VACUUM INTO) to~/.MemoryPilot/backups/memory/memory-before-v<version>.db(mode 600, the three latest copies kept), and the new binary opens a second copy with its schema upgrades (--self-test). Any failure stops the update and nothing is replaced. - The binary is replaced atomically; the previous one stays next to it as
MemoryPilot.old. Each running server switches to the new version in place as soon as it is idle (a second without a request over stdio, a few seconds over HTTP): the IDE keeps its connection, there is nothing to restart. - If the new version fails to start three times, the previous binary is put back and that version is skipped. The database is not rolled back automatically, because other servers may have it open: the copy from step 2 is there to restore by hand.
Releases roll out progressively: first to a share of installations (chosen from a random id kept in ~/.MemoryPilot/state/update/install-id, never sent), then to everyone after a delay, and a rollout can be paused. MemoryPilot update installs the latest release now, rollout and skipped versions aside; MemoryPilot update --check only reports it.
Not updated automatically: Homebrew installs (brew upgrade memorypilot), binaries inside a cargo target/ directory, debug builds, platforms without a release binary (Intel Macs, Windows), and any server started with MEMORYPILOT_AUTO_UPDATE=0. A binary installed with cargo install moves to the signed release binary at its first update. Installations of v4.11.0 or older do not have the updater yet: update them once by hand (install.sh again, or brew upgrade).
# Via Cargo, pinned to a release tag — works anywhere Rust runs
# (unsigned on macOS: Keychain prompt after each update if you store credentials):
cargo install --git https://github.com/Soflutionltd/MemoryPilot --tag v4.14.0 --bin MemoryPilot

# Local clone + auto-config (same installer, run from inside the repo):
git clone https://github.com/Soflutionltd/MemoryPilot.git && cd MemoryPilot && ./install.sh
The installer is idempotent: re-run it any time to refresh configs without breaking the others.
Every release ships pre-built binaries for the three mainstream targets. Linux builds come from the release CI workflow on every v*.*.* tag; the macOS build is signed with Soflution's Developer ID and notarized by Apple (scripts/release-macos.sh):
| Platform | Target triple | Archive |
|---|---|---|
| macOS Apple Silicon | aarch64-apple-darwin |
MemoryPilot-aarch64-apple-darwin.tar.gz |
| Linux x86_64 | x86_64-unknown-linux-gnu |
MemoryPilot-x86_64-unknown-linux-gnu.tar.gz |
| Linux arm64 | aarch64-unknown-linux-gnu |
MemoryPilot-aarch64-unknown-linux-gnu.tar.gz |
Each archive is paired with a .sha256 for verification. Grab them from the releases page.
Intel Mac (
x86_64-apple-darwin): no pre-built binary — theort/ ONNX Runtime crate used byfastembeddoes not publish prebuilts for this target. Usebrew install Soflutionltd/memorypilot/memorypilot(builds from source) orcargo install --git .... Apple Silicon Macs (M1+) are fully covered with a pre-built binary.
Supported IDEs / agents (auto-configured by ./install.sh):
| Agent | Config file / command | Auto-configured |
|---|---|---|
| Cursor | ~/.cursor/mcp.json |
✓ (stdio) |
| VS Code | ~/.vscode/mcp.json |
✓ (stdio) |
| Claude Desktop | ~/Library/Application Support/Claude/claude_desktop_config.json |
✓ (stdio) |
| Claude Code | claude mcp add |
✓ (CLI) |
| Codex CLI | codex mcp add |
✓ (CLI) |
| Gemini CLI | ~/.gemini/settings.json |
✓ (stdio) |
| Windsurf | ~/.codeium/windsurf/mcp_config.json |
✓ (stdio) |
| OpenCode | ~/.config/opencode/opencode.json |
✓ (stdio) |
| Cline (VS Code) | ~/Library/Application Support/Code/User/globalStorage/saoudrizwan.claude-dev/settings/cline_mcp_settings.json |
✓ (stdio) |
| Roo Code (VS Code) | ~/Library/Application Support/Code/User/globalStorage/rooveterinaryinc.roo-cline/settings/cline_mcp_settings.json |
✓ (stdio) |
| ChatGPT Desktop | Settings → Apps → Create | via HTTP (see below) |
Additional MCP-compatible clients (use the same stdio binary, manual config):
| Agent | Notes |
|---|---|
| Goose | YAML config under ~/.config/goose/config.yaml — add MemoryPilot under extensions: with type: stdio, cmd: ~/.local/bin/MemoryPilot |
| Kilo Code | Same cline_mcp_settings.json format under the Kilo VS Code extension storage path |
| Continue.dev | ~/.continue/config.json — add to mcpServers |
| Zed | Settings → Assistant → Context Servers → add stdio command |
| Aider | No native MCP; use the REST API (see HTTP API section) |
The script is idempotent — run it again to update without breaking existing MCP configs.
ChatGPT requires a remote MCP endpoint. Start the HTTP server, then add it as a custom connector:
MemoryPilot --http 7437In ChatGPT: Settings → Apps → Create → URL: http://localhost:7437/mcp
git clone https://github.com/Soflutionltd/MemoryPilot.git
cd MemoryPilot
cargo build --release --features http
cp target/release/MemoryPilot ~/.local/bin/
chmod +x ~/.local/bin/MemoryPilot
xattr -cr ~/.local/bin/MemoryPilot  # macOS only
Then add MemoryPilot to your IDE's MCP config manually (see table above for file paths).
That's it. MemoryPilot automatically injects a dynamic System Prompt into your IDE on startup. The AI will proactively call add_memory in the background to store your architecture decisions, API keys, and bug fixes without manual intervention. All configured IDEs share the same memory database.
For ChatGPT or any MCP client that needs HTTP: run MemoryPilot --http to expose the Streamable HTTP endpoint at /mcp.
Or use via McpHub for SSE transport with all your other MCP servers.
# If upgrading from v1 (JSON files):
MemoryPilot --migrate

# Compute embeddings for existing memories:
MemoryPilot --backfill

# Force re-embed all (skips unchanged via content hash):
MemoryPilot --backfill-force| Tool | Description |
|---|---|
recall |
Start here. Loads all context in one shot: project memories, scoped thread/window memories, preferences, critical facts, patterns, decisions, global prompt. Supports mode = safe/default/full, compact = true for AAAK compression. |
get_project_brain |
Instant project summary (<1500 tokens): tech stack, architecture, bugs, recent changes, components, team members. Supports compact = true. |
search_memory |
Hybrid BM25 + jina RRF search, boosted by importance, graph links, and file watcher context. Batched triple scoring. |
get_file_context |
Memories related to recently modified files in working directory. |
find_conversation |
Finds a past conversation from a vague description, across Cursor (every window, sub-agents folded into their conversation), Claude Code and Claude desktop agent sessions. Exact words and stems, misheard words (one or two letters off, split names glued back), and meaning, fused per conversation. Also finds conversations by a commit or a file they mention. Returns the matching message, commits, files and related memories. |
read_conversation |
Reads a found conversation, paginated, optionally centred on the matching message. |
search_in_conversation |
Searches inside one conversation and returns only the matching messages (id, role, date, snippet), so a conversation of thousands of messages is searched instead of paged through. |
log_external_request |
Records what was sent to a third party (forum post, bug report, support ticket, e-mail): destination, subject, URL, date, status and last reply. Updates a request when an answer arrives. |
pending_external |
Lists the requests still waiting for an answer, the longest-waiting first. They also open the recall of their project. |
| Tool | Description |
|---|---|
add_memory |
Store with lazy embedding, auto-dedup (hash exact + Jaccard 85%), auto entity extraction, auto graph linking, auto-classification (kind, importance, TTL inferred from content). |
add_memories |
Bulk add multiple memories in one call with per-item dedup. |
add_transcript |
Store a long transcript as chunked archive, auto-distill structured memories (decision, preference, todo, bug, milestone, problem, note). |
ingest_session |
Ingest local Claude/Cursor/session transcripts into the same MemoryPilot MCP. Defaults to distill_only=true, so only high-value memories are indexed. |
get_memory |
Retrieve by ID. |
update_memory |
Update content, kind, tags, importance, TTL. Skips re-embedding if content unchanged (hash check). |
delete_memory |
Delete by ID (cascades to entities and links). |
list_memories |
List with project/kind filters and pagination. |
MemoryPilot --install-hooksInstalls the hooks in every agent found (./install.sh runs it for you) (existing settings and hooks are kept, a .bak is written):
| Agent | File | Hooks | Context output |
|---|---|---|---|
| Cursor | ~/.cursor/hooks.json |
session start, session end | additional_context |
| Claude Code | ~/.claude/settings.json |
session start, user prompt, session end | hookSpecificOutput.additionalContext |
| Codex | ~/.codex/hooks.json |
session start | hookSpecificOutput.additionalContext |
- Session start runs
MemoryPilot --hook session-start --agent <agent>and injects the compact recall of the opened project. - Session start also runs
MemoryPilot --sync-agentsin the background (see below). When Cursor runs both its own hook and the Claude Code one, a session is served once. - User prompt (Claude Code
UserPromptSubmit) runsMemoryPilot --hook user-prompt --agent claude: the prompt the user just sent is searched in the store, and up to 3 memories that answer it are injected in full (4,000 characters at most). Only hits scoring at least 60% of the top hit are kept. Nothing is injected when the ranker abstains (confidence.abstain), for a slash command or a prompt of fewer than 4 words, for memories of another project, for credentials and raw transcripts, or for a memory already injected in the session. A session gets 10 memories at most, all prompts together: past that the hook returns at once, without searching. The search is the default one, cross-encoder rerank included: about 1 to 1.6 s per searched prompt on an M-series Mac (the models load in each hook process), nothing for a prompt that is not searched. - Session end (
SessionEnd, CursorsessionEnd) runsMemoryPilot --hook session-index --agent <agent>: the conversation index is brought up to date in a detached process, sofind_conversationsees the session that just ended. Nothing is distilled into memories.
MemoryPilot --install-hooks --with-ingestOpt-in: also distills every turn into memories.
- Stop runs
MemoryPilot --hook stop --agent <agent>, answers{}immediately and distills, in a detached process, only the transcript lines added since the previous turn. From user messages only what the user typed is kept (Cursor<user_query>, Claude Code meta lines skipped), agent narration ("Checking…", "Let me…", "Je vais…") is filtered out, and obvious secrets (API keys, JWTs, IBANs) are redacted before storage. - Session end then runs
MemoryPilot --hook session-end --agent <agent>: the same incremental ingest, for the lines the last stop did not cover, followed by the conversation index.
Running --install-hooks without --with-ingest removes the distilling hooks a previous install added.
State: ~/.MemoryPilot/state/cursor-hooks-state.json, ~/.MemoryPilot/state/prompt-injections/. Log: ~/.MemoryPilot/logs/cursor-hooks.log. Set MEMORYPILOT_DB=/path/copy.db to test against a copy.
./install.sh creates an empty ~/.MemoryPilot/agents/ and wires it into your tools. MemoryPilot ships no rules and no skills: write your own, once, for every agent.
~/.MemoryPilot/agents/
├── rules/AGENTS.md          your rules (starts as an example comment)
├── skills/<name>/SKILL.md   your skills (Agent Skills format)
├── vendor/<name>/SKILL.md   imported skills, linked like yours (yours win on a name clash)
└── plugins/<plugin>/          whole plugins (skills read over MCP)
MemoryPilot --setup-agents [--tools claude,cursor,codex,...] [--dry-run]
MemoryPilot --sync-agents                      # run by the session-start hook
MemoryPilot --uninstall-agents [--tools codex] # unwire, your files stay| Tool | Rules | Skills |
|---|---|---|
| Claude Code | @ import line in ~/.claude/CLAUDE.md (CLAUDE_CONFIG_DIR) |
link per skill in ~/.claude/skills/ |
| Codex | generated block in ~/.codex/AGENTS.md (CODEX_HOME) |
~/.agents/skills/ |
| Gemini CLI | @ import line in ~/.gemini/GEMINI.md (GEMINI_CLI_HOME) |
~/.agents/skills/ |
| Cursor | generated ~/.cursor/rules/agents.mdc |
~/.agents/skills/, or none when Claude Code is wired (Cursor reads ~/.claude/skills) |
| VS Code Copilot | generated block in ~/.copilot/copilot-instructions.md |
~/.agents/skills/ |
| OpenCode | path added to instructions in ~/.config/opencode/opencode.json (OPENCODE_CONFIG_DIR) |
~/.agents/skills/ |
| Cline | link ~/Documents/Cline/Rules/memorypilot-agents.md |
~/.agents/skills/ |
| Roo Code | link ~/.roo/rules/memorypilot-agents.md |
~/.agents/skills/ |
| Windsurf / Devin | reads ~/.claude/CLAUDE.md |
~/.agents/skills/ |
- Only detected tools are offered. Interactive
./install.shasks which ones (Enter = all); without a terminal, or with--yes, only Claude Code is wired unless--agents-tools=claude,codexsays otherwise../install.sh --uninstall-agents [--tools ...]undoes. - Nothing is overwritten: an existing
agents/folder is left as is, a skill name already taken in a tool is skipped and reported, aCLAUDE.mdthat is a symbolic link is not written (Claude Cowork ignores linked ones). agents/.manifest.jsonrecords every link, line, block and generated file with its fingerprint.--sync-agentswrites nothing while AGENTS.md and the skill list are unchanged, never fails (errors go to~/.MemoryPilot/logs/agents-sync.log), and leaves hand-edited copies alone.--uninstall-agentsremoves only what the manifest lists and is still unmodified.- Claude Desktop (chat) cannot be wired: its rules and skills live in your claude.ai account.
- Plugins: a whole plugin goes in
agents/plugins/<name>/(Claude Code format:.claude-plugin/plugin.json,skills/,agents/,hooks/). Claude Code installs it natively as<name>@memorypilotfrom a generated local marketplace (plugins/.claude-plugin/marketplace.json); a content change runsclaude plugin marketplace updateandclaude plugin updateat the next sync. When the folder also holdscursor/(.cursor-plugin/plugin.json), Cursor gets that variant linked into~/.cursor/plugins/local/<name>; otherwise the other tools get the plugin's skills in~/.agents/skills/. A failedclaudecall is retried at the next session. agents/catalog.json, rewritten by every--setup-agentsand--sync-agentswhen it changes, lists each rule, skill, plugin and McpHub MCP server:type,origin(perso, vendor, or external for a skill of~/.claude/skillsor~/.cursor/skillsleft to the tool that installed it, withmanaged_by),version,sourceandurlfor vendor items,targets(Claude Code, Cursor, Claude app throughget_agent_skill),updatedandstatus(ok,partial,not_deployed). MCP servers are listed by name only: their arguments and environment are never copied.- Vendor plugins carry
plugin.source.json(repo,commit, optionalbranch,claudeandcursorfolders in the repository).MemoryPilot --update-plugins [name]fetches the upstream head and prints the diff (full diff inplugins/.updates/<name>.diff); nothing changes until--update-plugins <name> --apply, which keeps the previous copy inplugins/.backups/(3 per plugin). - Over MCP,
list_agent_skillsreturns every skill (name, description, origin:perso,vendororplugin:<name>) andget_agent_skill(name, file?)returns itsSKILL.mdand the list of its other files, or one of them such asreferences/guide.md(never a path outside the skill folder). The serverinstructionscarry the skill names, so a client that does not read the folder (Claude app, remote access) still knows they exist. Plugin skills (agents/plugins/<plugin>/skills/<name>/SKILL.md) are named<plugin>:<name>.
MemoryPilot --add-skill vercel-labs/skills@find-skills          # fetch for review, install nothing
MemoryPilot --add-skill vercel-labs/skills@find-skills --apply  # install the copy you just reviewed
MemoryPilot --update-skills                                     # what changed upstream, for every imported skill
MemoryPilot --update-skills find-skills --apply                 # install a reviewed update
--add-skill takes owner/repo (GitHub), owner/repo@skill, or any Git URL, with --skill NAME, --path DIR and --branch B when the repository needs them. A repository holding several skills lists them. The first run only stages the skill in ~/.MemoryPilot/agents/vendor/.updates/<name>/ and prints its files (anything that is not plain text is flagged), or the diff with the copy you already have. Nothing a skill ships is run, and symbolic links are left out. --apply then moves that exact copy to agents/vendor/<name>/, keeps the previous one in agents/vendor/.backups/ (3 kept), and syncs every wired tool, so the skill reaches Claude Code, Cursor and the others the same way your own skills do.
skill.source.json next to SKILL.md records the repository, the commit and the folder; --update-skills follows it. A skill copied by hand has no such file: --add-skill owner/repo@name adopts it, showing the diff with upstream first. A skill of yours with the same name in agents/skills/ always wins, and --apply refuses to add a vendor skill it would hide.
Off by default. To let the adopted skills and plugins update by themselves, write {"auto": true} in ~/.MemoryPilot/config/agents-updates.json (or set MEMORYPILOT_AGENTS_AUTO_UPDATE=1). A session start then launches MemoryPilot --auto-update in the background, once a day at most; the command can also be run by hand at any time.
MemoryPilot --auto-update              # one run now
MemoryPilot --rollback-update NAME     # put the previous copy back; that version is not installed again
Nobody reads a diff, so three rules do:
- Only what you adopted. A skill or plugin is followed when it has a
skill.source.jsonorplugin.source.json. Nothing new is ever added. - A delay. An upstream version is installed once this machine has seen it unchanged for 3 days (
"delay_days"in the same file). The delay runs from what was observed here, not from commit dates, which their author chooses. A hijacked repository is usually put right within days; the reverted version is then the one installed. - A check of what the update adds. It is held back, and the stored copy stays, when it adds or changes a script or a binary; when a JSON, YAML or TOML file changes what it makes a tool run or reach (hooks, servers, commands, their arguments, environment and URLs; JSON keys are decoded first, a file that cannot be parsed is held); when the front matter of a Markdown file changes anything other than its description (tools, hooks, model, permission mode); or when it adds a line that downloads and runs code, sends a local file to a server, reads credentials, opens a remote shell, hides characters, or tells the agent to act behind the user's back. Symbolic links of the upstream repository are never copied.
The background run stages in .updates-auto/, apart from .updates/, which only ever holds a copy you asked to read. The next session start says in one line what was updated and what was held back, once; the model is given the names of your folders only, the reasons (which quote upstream file names) are shown to you. To read a held version, run --update-skills NAME or --update-plugins NAME, then --apply it if it is fine. Every replaced copy is kept in .backups/.
To lift the check, not the delay, for an author you vouch for (a plugin whose every release ships scripts), name its folder: {"auto": true, "trusted": ["name"]}. Its updates then install after the delay with nothing read by anyone, so name only what you would run unread anyway.
What the check cannot do: it reads for what can run and for known tricks, it does not understand prose. A harmful instruction written as ordinary guidance passes it, and so does a command spelled in a way it does not know. The delay is the guard for those cases, not the check. A plugin that ships scripts is held at each release that changes them, by design.
| Tool | Description |
|---|---|
kg_add |
Add a fact triple (subject → predicate → object) with optional validity period and confidence score. |
kg_invalidate |
Mark a triple as expired (sets valid_to), preserving history. |
kg_query |
Query all triples related to an entity, with temporal filtering and direction control. |
kg_timeline |
Chronological history of all triples involving an entity. |
kg_stats |
Summary statistics: total triples, active, expired, unique subjects/objects. |
| Tool | Description |
|---|---|
get_project_context |
Full project context with preferences and patterns. |
register_project |
Register project with filesystem path for auto-detection. |
list_projects |
List projects with memory counts. |
get_stats |
DB statistics: totals, by kind, by project, DB size, hygiene signals. |
get_global_prompt |
Auto-discover GLOBAL_PROMPT.md from ~/.MemoryPilot/config/ or project root. |
export_memories |
Export as JSON or Markdown with importance stars. |
set_config |
Set config values (e.g. global_prompt_path). |
| Tool | Description |
|---|---|
run_gc |
Garbage collection: merge old memories, clean orphans, vacuum. Supports dry_run. |
compact_memories |
Compress old low-importance memories into dense capsules (~100-200 tokens). Credentials/architecture never compressed. |
cleanup_expired |
Remove expired TTL memories (debounced — runs max once per 60s). |
pin_memory |
Pin a critical memory — always included in recall, never garbage collected. |
unpin_memory |
Unpin a previously pinned memory, making it eligible for GC again. |
find_related |
Find all memories related to a given ID via Knowledge Graph traversal (depth 1-3). |
bulk_delete |
Delete memories by kind, project, tag, age, or importance. Never touches pinned memories. |
get_memory_health |
Health report: distribution by kind/project/importance, stale count, orphans, compression potential, DB size. |
dedupe_report |
Find potential duplicates via Jaccard similarity for manual review. |
consolidate_memories |
Fold near-duplicate ephemeral memories (embedding cosine ≥ threshold, same project, never decisions/credentials/pinned) into their newest member — tags, importance, access counts and graph links merged. Dry-run by default, apply: true to execute; also runs automatically once a day. |
analyze_corpus |
Inspect text without writing memory: origin, platform, agents/personas, and reliable topics. |
benchmark_recall |
Recall quality benchmark with golden scenarios. |
benchmark_search |
Search quality benchmark: R@5, R@10, NDCG@10, cluster coherence, latency. |
migrate_v1 |
Import from v1 JSON files. |
fact · preference · decision · pattern · snippet · bug · credential · todo · note · milestone · architecture · problem · transcript_chunk
Each memory has importance (1-5), optional TTL, tags, project scope, content hash, and auto-generated embedding + entity links.
MemoryPilot                          # Start MCP stdio server
MemoryPilot --backfill               # Compute missing embeddings
MemoryPilot --backfill-force         # Re-embed all (skips unchanged via hash)
MemoryPilot --benchmark-recall       # Run recall quality benchmark
MemoryPilot --benchmark-search       # Search quality: R@5, R@10, NDCG@10, cluster coherence
MemoryPilot --benchmark-fr           # French/multilingual deterministic benchmark (109 queries, ±1pp variance)
MemoryPilot --benchmark-longmemeval  # LongMemEval-S benchmark, supports --limit N and --min-r5 PCT
MemoryPilot --benchmark-concurrency  # Multi-client concurrency bench (--clients N --queries-per-client N)
MemoryPilot --benchmark-latency      # open_at startup + search latency
MemoryPilot --http 7437              # Start HTTP REST server (requires --features http)
MemoryPilot --migrate                # Import v1 JSON data
MemoryPilot update [--check]         # Install the latest release now (--check: only report it)
MemoryPilot --self-test DB           # Open DB with this version's schema upgrades (used by the updater on a copy)
MemoryPilot --version                # Show version
MemoryPilot --help # Show help| Variable | Default | Effect |
|---|---|---|
MEMORYPILOT_CROSS_RERANK |
adaptive |
1/always to force rerank on every query, 0/off to disable. Adaptive rerank fires on hard / non-English queries. |
MEMORYPILOT_CROSS_RERANK_TOP_K |
12 |
Number of candidates the cross-encoder rescores. |
MEMORYPILOT_CROSS_RERANK_WEIGHT |
1.0 |
Fusion weight given to the cross-encoder score against the RRF score, bounded to 0-1. At 1.0 the reranked candidates are ordered by the cross-encoder alone. Measured with multilingual-reranker-small (Apple M2 Max): --benchmark-fr R@1 98.2% at 1.0 and 96.3% at 0.6. |
MEMORYPILOT_RERANK_POOL_SIZE |
1 |
Number of cross-encoder ONNX sessions kept hot. 2 helps only under heavy concurrent load; each extra session costs ~140 MB. |
MEMORYPILOT_EMBED_POOL_SIZE |
1 |
Number of embedding ONNX sessions in the pool. A second jina session adds ~250 MB and only pays off under heavy concurrent writes. |
MEMORYPILOT_EMBED_THREADS |
min(4, cores) |
ONNX intra-op threads for the embedder. MEMORYPILOT_RERANK_THREADS (default min(2, cores)) does the same for the cross-encoder. |
MEMORYPILOT_RERANKER_MODEL |
horizon-small |
Horizon Labs' multilingual-reranker-small int8 (268 MB, memory-mapped, Apache-2.0, 47 languages), the only cross-encoder. Its files are fetched from the model-horizon-small-v1 release of this repository, checked against a pinned SHA-256, with the publisher's pinned revision as a fallback. |
MEMORYPILOT_MODEL_IDLE_SECS |
600 |
Idle time after which the embedder and reranker sessions are dropped to free memory (~250 MB). 0 keeps them resident (benchmarks). |
MEMORYPILOT_CONSOLIDATE |
on |
Daily embedding-based consolidation of near-duplicate ephemeral memories (cosine ≥ 0.95 and word overlap ≥ 0.6, same project, newest kept), followed by the supersede pass (see v4.6). off disables it; consolidate_memories runs it on demand. |
MEMORYPILOT_MMR / MEMORYPILOT_MMR_LAMBDA |
on / 0.4 |
MMR diversity over the finalists. 0 disables; λ = 1.0 is pure relevance, 0.0 pure diversity. MEMORYPILOT_MMR_FLOOR (0.55) is the cosine below which two candidates are not considered redundant. |
MEMORYPILOT_TEMPORAL |
on |
Query-time date window boost/demotion. 0 disables (date entities are still extracted at ingest). |
MEMORYPILOT_ABSTAIN_COSINE / MEMORYPILOT_TRUST_CROSS |
0.35 / -2.0 |
Below the cosine floor a search reports confidence.abstain = true unless the cross-encoder logit on the top hit reaches the trust value. |
MEMORYPILOT_READER_NULL_MARGIN |
0 |
Extractive reader: the span logit must beat the model's no-answer logit by this much. Negative values answer more often (−3 → 92/100 answered, 3/7 abstentions still caught on LongMemEval-S@100). |
MEMORYPILOT_AUTO_UPDATE |
on |
0/off stops the server from checking for and installing new releases (see Automatic updates). MemoryPilot update still works by hand. |
MEMORYPILOT_EMBED_MODEL |
jina |
jina-embeddings-v5-text-nano-retrieval int8 (768-dim), the only embedder since v4.11. jina-q4 = its 4-bit variant (140 MB download, faster queries, about 1 pp lower R@5 and 3 pp lower MRR on FR). The database records which model produced its vectors; a database built with another model is re-embedded once in the background at next start (BM25 keeps answering meanwhile). |
When built with --features http, MemoryPilot exposes a multi-threaded REST API (4 worker threads, each with its own DB connection):
# Health check
curl http://localhost:7437/health

# Call any MCP tool
curl -X POST http://localhost:7437/tools/call \
  -H 'Content-Type: application/json' \
-d '{"name": "search_memory", "arguments": {"query": "auth setup", "limit": 5}}'src/main.rs — CLI + MCP stdio server + file watcher init + HTTP server init + benchmark runners
src/code_chunker.rs — Tree-sitter code-aware chunking for Rust/Python/TS/TSX/JS/Go/Java/Kotlin/Swift + Svelte scripts
src/db.rs — SQLite facade: hybrid search, CRUD, KG, GC, brain, recall, lazy embed, connection pool, ANN warm-up
src/db/benchmark.rs — Internal recall/search quality benchmark helpers
src/db/benchmark_fr.rs — French/multilingual deterministic benchmark (109 queries, ±1pp variance)
src/db/benchmark_longmemeval.rs — LongMemEval-S benchmark runner + regression guard support
src/db/transcript.rs — Transcript/session ingestion and local-only distillation
src/tools.rs — 41 MCP tool definitions + handlers
src/protocol.rs — JSON-RPC types
src/embedding.rs — jina-embeddings-v5 via ONNX Runtime (fastembed for legacy models), EmbedPool, two-tier query cache
src/tokenizer.rs — lean byte-level BPE (tiktoken ranks) and merge BPE tokenizers, a fraction of the memory of the `tokenizers` crate
src/onnx_external.rs — one-shot rewrite of embedded ONNX weights into a memory-mapped sidecar (ORT 1.28 keeps 3 copies otherwise)
src/pool.rs — lazily-built, idle-evicting pool shared by the embedder and reranker sessions
src/db/consolidate.rs — embedding-based near-duplicate consolidation (daily + `consolidate_memories`)
src/reranking.rs — Cross-encoder rerank (multilingual-reranker-small), RerankPool, adaptive trigger, confidence gate
src/model_mirror.rs — model files served from a release of this repository, pinned by size and SHA-256
src/ann.rs — Persistent on-disk HNSW (usearch) with synchronous warm-up via `wait_for_ann_warm`
src/fts.rs — FTS5 query variants (prefix, phrase, NEAR) + Snowball stemming
src/graph.rs — Entity extraction (tech, files, components, people) + relation inference + graph traversal
src/gc.rs — GC scoring, heuristic memory merging, stopwords
src/working_memory.rs — In-process scoped scratchpad memory for current MCP sessions
src/watcher.rs — File system watcher + auto-linter with persistent DB connection
src/http.rs — Optional multi-threaded HTTP REST server (feature-gated)
memories           — id, content, kind, project, tags, importance, embedding (BLOB),
                     content_hash, expires_at, last_accessed_at, access_count, metadata
memories_fts       — FTS5 virtual table (content, tags, kind, project)
memory_entities    — memory_id, entity_kind, entity_value, valid_from, valid_to
memory_links       — source_id, target_id, relation_type, valid_from, valid_to, confidence
knowledge_triples  — id, subject, predicate, object, valid_from, valid_to, confidence, source_memory_id
projects           — name, path, description
config — key/value store| Metric | Value |
|---|---|
| Binary size | 35 MB |
Startup (open_at) |
1-2 ms (ANN warm-up runs in background) |
Startup (open_at_warm) |
50-200 ms on 10 k memories (ANN hydrated synchronously, deterministic search from query #1) |
| Search with rerank off (BM25 + RRF) | ~28 ms avg on LongMemEval-S (v4.2, search call only) |
| Search adaptive cross-encoder | v4.11 (jina-reranker-v2): ~436 ms avg on --benchmark-fr on a 2-vCPU Linux VM, R@5 100%, MRR 98.0%. v4.10 (mmarco): ~210 ms on an Apple Silicon Mac, R@5 99.1%, MRR 97.4% |
| Concurrency p95 (4 clients × 20 queries, 500 memories, adaptive) | 229 ms |
add_memory latency |
<1 ms (lazy embed) |
| Embedding quality | Transformer 768-dim (jina-embeddings-v5-text-nano-retrieval int8, 100+ languages, 8k context) |
| Backfill (1000 memories) | ~2 min in the background (model swap re-embed; recall stays interactive, ~1 s, while it runs) |
| RAM (both models loaded, steady state) | ~370 MB on a fresh database, ~485 MB with 2 000 memories in the ANN index — almost all of it memory-mapped int8 weights (247 MB embedder + 268 MB reranker) the OS can reclaim under pressure (was ~3.5 GB idle / ~7 GB peak in v4.3) |
| RAM (idle) | ~130 MB: both ONNX sessions are released after MEMORYPILOT_MODEL_IDLE_SECS (default 600 s) without a query and rebuilt on the next one (~0.8 s once, ~0.3 s for the reranker alone) |
RAM (--benchmark-fr, peak) |
364 MB (was 7.05 GB) |
| Read concurrency | 16 pooled connections per Database handle |
| Runtime dependencies | None (ONNX bundled) |
- Lazy embedding:
add_memoryinserts withNULLembedding, background thread computes and updates asynchronously - Content hashing (FNV-1a):
--backfill-forceskips memories whose content hasn't changed - Two-tier embedding cache: 256-entry in-process LRU on top of a write-through SQLite query cache (
*.query_cache.sqlite, soft-capped at 8 192 entries with LRU eviction) so repeated queries are instant within a session and across restarts - Read connection pool (4 connections): concurrent vector searches don't block writes
- WAL mode: SQLite Write-Ahead Logging for concurrent read/write
- Batched scoring: knowledge triple counts and link boosts fetched in single queries, not N+1
- Debounced cleanup: expired memory cleanup runs max once per 60 seconds
- Prepared statements: graph traversal prepares SQL once, not per node
- Tuned RRF fusion: k=40 for sharper top-K discrimination vs standard k=60
- FTS5 precision fallbacks: prefix, exact phrase, and NEAR proximity queries run together for code symbols, errors, and named concepts
- Weighted FTS fields: content, tags, kind, and project use separate BM25 weights to make structured metadata count
- ACT-R-style activation: frequently reused and recently accessed memories get a small cognitive activation boost before final reranking
- int8 quantized embeddings: stored vectors are 4× smaller (388 bytes vs 1536 bytes) with negligible recall loss; fast SIMD-friendly dot product directly on the blob avoids per-search allocations
- Local HNSW ANN index (
usearch): persistent on-disk approximate nearest neighbor index that warms asynchronously from SQLite in a detached thread (non-blocking startup), updates incrementally on backfill, on the async embed worker, and on delete. Surfacesvector_anncandidates so large memory bases stay fast as they grow past tens of thousands of entries. - ANN scan bypass: when the index reaches 5,000+ entries, the SQL vector scan is restricted to the union of ANN top-K and BM25 hits — turning an O(N) blob load into an O(K) lookup without changing the ranking logic.
- Code-aware chunking: tree-sitter splits Rust/Python/TypeScript/TSX/JavaScript on semantic units, with Svelte
<script>extraction - Exact term coverage boost: +10% when 80%+ of query terms appear in memory content
- Combinatorial reranker: greedy subgraph selection, conservative +5% per connection (cap 15%)
- KG query expansion: post-retrieval scoring boost from knowledge graph related terms (+4% per entity, cap 15%)
- Temporal recency: gentle +5% for memories from last 3 days, decaying over 30 days
- Importance tiebreaker: ±3% per level — never overrides relevance signal
- Adaptive cross-encoder reranking (multilingual-reranker-small via ONNX Runtime, default ON): triggers on hard / non-English queries, orders the reranked candidates by its score (tunable weight), drops cleanly to BM25+RRF on easy English queries to stay under 30 ms. Pool of N sessions (
MEMORYPILOT_RERANK_POOL_SIZE) absorbs concurrent load. - Confidence gate: skips rerank when the top-1 RRF score is already ≥ 25 % above top-3 (latent path; active when force-rerank is enabled)
- Auto-compaction: GC triggers automatically when memory count > 500, debounced to once per 5 minutes
- Memory capsules: old low-importance memories compressed into ~100-200 token summaries (5-10x savings)
- Zero-shot auto-classification: pattern-based heuristics assign kind, importance, and TTL on insert without LLM
Use cargo check for day-to-day validation; it catches type and borrow errors without paying the full linking cost.
make check          # cargo check
make check-http     # cargo check --features http
make test           # cargo test
make timings        # cargo build --timings
make check-cached   # RUSTC_WRAPPER=sccache cargo check
sccache is optional but recommended for frequent rebuilds:
make sccache-install
make build-cached
Cargo aliases are also available: cargo dev, cargo check-http, cargo test-fast, cargo timings, and cargo build-http.
Keep cargo build --release --features http for release validation and benchmark runs. Linker swaps such as mold or lld are intentionally not enabled by default on macOS; measure with cargo build --timings first before changing .cargo/config.toml.
MemoryPilot --benchmark-search --scenario-limit 30    # R@5, R@10, NDCG@10, cluster coherence, latency
MemoryPilot --benchmark-recall --scenario-limit 12    # top1/top5 hit rate, cross-project leak, credential safety
MemoryPilot --benchmark-longmemeval [PATH] [--limit N] [--min-r5 PCT] # LongMemEval-S with regression guard
The LongMemEval benchmark downloads the LongMemEval-S dataset and evaluates retrieval quality across 470 questions with turn-level granularity. Results are output as JSON with per-category breakdowns.
The cross-encoder runs in adaptive mode by default (triggers on hard / non-English queries). Force or disable it explicitly:
MEMORYPILOT_CROSS_RERANK=off MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json     # baseline, ~28ms/query, 98.7% R@5
MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json                                 # adaptive (default), ~900ms/query, 99.1% R@5
MEMORYPILOT_CROSS_RERANK=1 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json      # force on every query, max latency
MEMORYPILOT_CROSS_RERANK_WEIGHT=0.70 MemoryPilot --benchmark-longmemeval benchmarks/longmemeval_s_cleaned.json  # bias more toward the cross-encoder score
The cross-encoder is multilingual-reranker-small (the figures that follow were measured with earlier cross-encoders). Validated full-run results on the 470 evaluable LongMemEval-S questions (v4.2, session-level recall_any): with the rerank off, 98.7% R@5, 95.1% NDCG@10, 93.6% MRR, ~28 ms average search latency; adaptive mode reaches 99.1% R@5, 96.0% NDCG@10, 94.9% MRR, ~900 ms average search latency. The deterministic French benchmark (--benchmark-fr) is the canonical regression test for any multilingual change — variance is bounded to ±1 pp R@5 across runs.
- Database:
~/.MemoryPilot/data/memory.db - Global prompt:
~/.MemoryPilot/config/GLOBAL_PROMPT.md
~/.MemoryPilot/
├── data/      memory.db, conversations.db (+ WAL, vector index, query cache)
├── state/     hook state, session-start injections (read by McpHub), update state
├── config/    http.token, credentials.key, known-secrets.sha256, GLOBAL_PROMPT.md
├── logs/      every log
├── backups/   memory/ (copies before an update, three kept) and your own
├── archive/   archived transcripts, v1 files, old copies
└── agents/    rules, skills, plugins
An older layout (everything at the root) keeps working. MemoryPilot --migrate-layout shows the plan, --apply sorts the files (it refuses while another process holds a database open, copies memory.db to backups/memory/memory-before-layout.db first and leaves symbolic links at the old paths read by older binaries and McpHub).
- Model cache:
~/.cache/fastembed/(Hugging Face layout, downloaded on first run;FASTEMBED_CACHE_PATHoverrides). Externalized ONNX weights live inmemorypilot-external/inside it.
Soflution Source Available License: free to use, not to fork or modify. See LICENSE for details.
MemoryPilot runs two models:
- jina-embeddings-v5-text-nano-retrieval (embeddings), by Jina AI, downloaded from their Hugging Face repository on first use and never redistributed by MemoryPilot. It is licensed under CC-BY-NC-4.0: non-commercial use only. Personal use is fine. Commercial use, including inside a company or a paid product, needs a commercial licence from Jina AI.
- multilingual-reranker-small (reranking), Copyright 2026 Horizon Labs, Apache License 2.0, fine-tuned from mmBERT-small (MIT, Johns Hopkins University CLSP). Its int8 graph and tokenizer are mirrored unmodified, with their
LICENSEandNOTICE, in themodel-horizon-small-v1release of this repository.
The opt-in answer reader (answer: true) uses deepset/roberta-base-squad2, CC-BY-4.0.
Built by SOFLUTION LTD